CITE THIS NOTEBOOK: Implementing Deep Q-Networks (DQN) algorithm by Mikel Landajuela. Wolfram Community 2021.
ORIGINAL ARTICLE: Mnih, V., Kavukcuoglu, K., Silver, D. et al. Human-level control through deep reinforcement learning. NATURE 518, 529-533 (2015). https://doi.org/10.1038/nature14236.
ORIGINAL ARTICLE: Mnih, V., Kavukcuoglu, K., Silver, D. et al. Human-level control through deep reinforcement learning. NATURE 518, 529-533 (2015). https://doi.org/10.1038/nature14236.
Introduction
Introduction
In this post, we implement the original DQN algorithm from Mnih, V., Kavukcuoglu, K., Silver, D. et al. Human-level control through deep reinforcement learning. Nature 518, 529–533 (2015) using experience replay and fixed Q-targets. In a nutshell, the DQN algorithm reads:
Fori=0,…,T:
|
Load the CartPole environment
Load the CartPole environment
In[]:=
env=DeviceOpen["SimulatedCartPole"]
Out[]=
In[]:=
Clear[Qnet,decode,buffer,sampleAction,QLoss,QnetTarget,CollectTransitions];
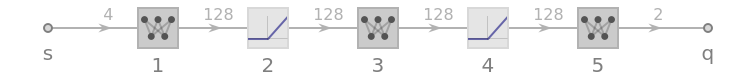
The Q Network () is defined as:
Q(s)=(,)
q
a
1
q
a
2
In[]:=
Qnet=NetInitialize@NetGraph[{LinearLayer[128],ElementwiseLayer["ReLU"],LinearLayer[128],ElementwiseLayer["ReLU"],LinearLayer[2]},{NetPort["s"]12345NetPort["q"]},"s"4];Information[Qnet,"SummaryGraphic"]
Out[]=
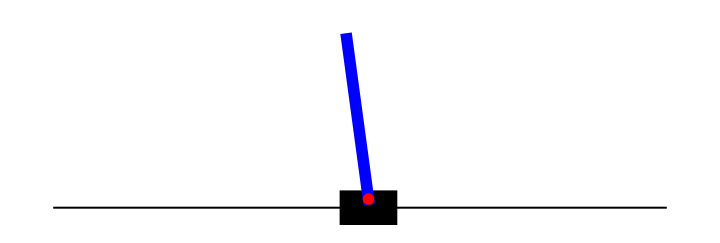
Test the poor performance of the Q network without training
Test the poor performance of the Q network without training
In[]:=
DeviceExecute[env,"Reset"];decode[i_]:={Left,Right}[[i]];ListAnimate[Table[(DeviceExecute[env,"Step",decode@Ordering[Qnet[DeviceRead[env]["ObservedState"]]][[-1]]];DeviceExecute[env,"Render"]),500]]
Out[]=
Sampling action according to ϵ-greedy policy
Sampling action according to ϵ-greedy policy
In[]:=
sampleAction[Qnet_,obs_,epsilon_]:=Module[{out,coin},out=Qnet[obs];coin=RandomReal[];If[coin<epsilon,Return[RandomInteger[{1,2}]],Return[Ordering[out][[-1]]]]];
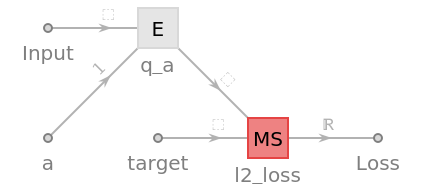
The Q-loss is
The Q-loss is
In[]:=
QLoss=NetGraph[{"q_a"ExtractLayer[],"l2_loss"MeanSquaredLossLayer[](*"l1_loss"MeanAbsoluteLossLayer[]*)},{{NetPort["Input"],NetPort["a"]}"q_a",{"q_a",NetPort["target"]}"l2_loss"(*{"q_a",NetPort["target"]}"l1_loss"*)},"a"1];Information[QLoss,"SummaryGraphic"]
Out[]=
In[]:=
bufferLimit=50000;bufferInitial=2000;QnetTarget=Qnet;(*InitializetheQ-target*)gamma=0.98;updateQTargetInterval=20;batchsize=32;learningrate=0.0005;maxtrainingrounds=1500;
Replay buffer
Replay buffer
buffer=CreateDataStructure["Deque"];PutInMemory[tuple_]:=Module[{},If[buffer["Length"]≥bufferLimit,buffer["PopFront"]];buffer["PushBack",tuple];];initialround=1;
Initialize the buffer
Initialize the buffer
While[buffer["Length"]<bufferInitial,epsilon=Max[0.01,0.08-0.01*(initialround/200)];(*Linearannealingfrom8%to1%*)(*Starteachnewepisodewithafreshenvironment*)s=DeviceExecute[env,"Reset"]["ObservedState"];(*Episodeloop*)done=False;score=0;While[¬done,{action=sampleAction[Qnet,s,epsilon];{sprime,r,done}=Lookup[DeviceExecute[env,"Step",decode@action],{"ObservedState","Reward","Ended"}];doneMask=If[done,0.0,1.0];tuple={s,action,N@r/100,sprime,doneMask};PutInMemory[tuple];s=sprime;}];initialround++;];
In[]:=
CollectTransitions[env_,Qnet_,buffer_,gamma_,round_,batchSize_,updateQTargetInterval_]:=Module[{epsilon,done,s,sprime,r,doneMask,tuple,score,action,transitions},epsilon=Max[0.01,0.08-0.01*((round+initialround)/200)];(*Linearannealingfrom8%to1%*)(*Starteachnewepisodewithafreshenvironment*)s=DeviceExecute[env,"Reset"]["ObservedState"];(*Episodeloop*)done=False;score=0;While[¬done,{action=sampleAction[Qnet,s,epsilon];{sprime,r,done}=Lookup[DeviceExecute[env,"Step",decode@action],{"ObservedState","Reward","Ended"}];doneMask=If[done,0.0,1.0];tuple={s,action,N@r/100,sprime,doneMask};PutInMemory[tuple];score+=r;s=sprime;}];(*EveryupdateQTargetIntervalupdatethetargetnetworkQnetTarget*)If[Mod[round,updateQTargetInterval]0,QnetTarget=Qnet];transitions=RandomChoice[Normal[buffer],batchSize];transitions=Map[{#[[1]],{#[[2]]},#[[3]]+gamma*Max[QnetTarget[#[[4]]]]*#[[5]]}&,transitions];<|"s"transitions[[All,1]],"a"transitions[[All,2]],"target"transitions[[All,3]],"score"score|>];
Training the network
Training the network
Score increases with training
Score increases with training
Test that trained Q network is doing the job
Test that trained Q network is doing the job