Generate Problems
Generate Problems
In[]:=
x_
p__
In[]:=
pr=PlotRange{{0,4},{0,4}};lo={1,1};hi={3,3};gen:=RandomInstance[GeometricScene[{a,b,c},{CircleThrough[{a,b,c}],Point[a]∈Rectangle[lo,hi],Point[b]∈Rectangle[lo,hi],Point[c]∈Rectangle[lo,hi]}]]z=genρ=r=Rectangle@@,,,;i=3(*activepoint*);
z
1,1,;;3
All,2
pr
2,1,1
pr
2,2,1
pr
2,1,2
pr
2,2,2
Out[]=
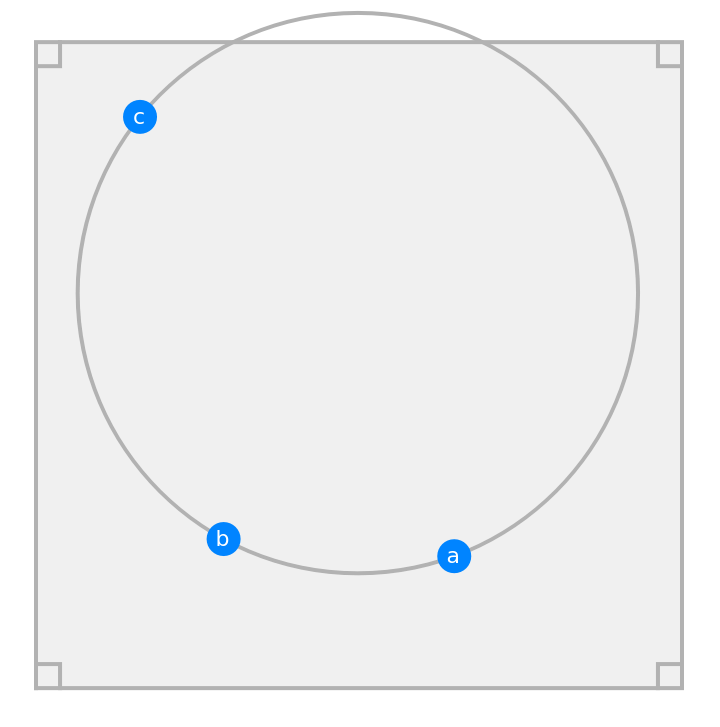
Out[]=
{{2.29487,1.40843},{1.58084,1.46154},{1.32209,2.76856}}
Define DeviceClass Functions
Define DeviceClass Functions
In[]:=
state=s="ObservedState";ended=e="Ended";reward="Reward";points=3;actions={Left,Right,Up,Down};f=False;t={2,2};l={0,4};finished:=Withe=f||~ContainsAny~l,If[e,f=e];erandom:=RandomChoice@actionsreset:=f=False;z=gen;ρ=;best=t~EuclideanDistance~ρi;readread:=<|staterender,endedfinished|>render:=ImageRotateImageSparseArrayClipRound10,{1,64}1,40,0,90°Δ=.1;Δσ=<|Left{-Δ,0},Right{+Δ,0},Down{0,-Δ},Up{0,+Δ}|>;
ρ
i
z
1,1,;;points
All,2
ρ
i
In[]:=
step//ClearAllstep[a_]:=Module[{o,n,β,e,r},o=ρ〚i〛;n=If[f,o,ρ〚i〛=Clip[o+Δσ[a],l]];β=t~EuclideanDistance~n;e=finished;r=If[e,0,If[best≤β,0,best=β;1]];<|staterender,endede,rewardr,"Best"best|>]
Test Human interactions
Test Human interactions
In[]:=
joystick:=Grid[({{,Button["↑",last=step@Up],},{Button["←",last=step@Left],Button["",last=reset],Button["→",last=step@Right]},{,Button["↓",last=step@Down],}}),Spacings{0,0}]
In[]:=
last=reset;(*←→↑↓*)joystick{last//Dataset,best}//Column//Dynamic
Out[]=
| | |
| |
Out[]=
best |
Define Neural Networks for Reinforcement Learning
Define Neural Networks for Reinforcement Learning
from Wolfram Mathematica website for CartPole demo
from Wolfram Mathematica website for CartPole demo
Loss Function
Loss Function
In[]:=
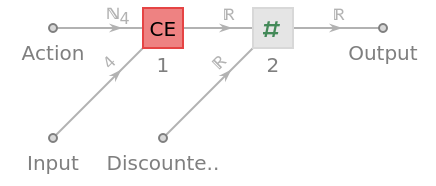
NeuralNetworks`Private`$ExpandNetSummaryBoxByDefault=True;netSize=Dataset@NetInformation[#,{"ArraysElementCounts","ArraysTotalElementCount","ArraysTotalSize"}]&;actionClass={"Class",actions(*{Left,Right,Up,Down}*)};loss=NetGraph[{1CrossEntropyLossLayer["Index"],2ThreadingLayer[#1*#2&]},{NetPort["DiscountedReward"]2,{NetPort["Input"],NetPort["Action"]}12},"Action"NetEncoder[actionClass]]loss//netSize
Out[]=
NetGraph



Policy Network - !! DOES NOT CONVERGE !!
Policy Network - !! DOES NOT CONVERGE !!
Train - !! DOES NOT CONVERGE !!
Train - !! DOES NOT CONVERGE !!