We describe an algorithm for computing the K-th power of an arbitrary square matrix A ∈ () that combines four classical ingredients: the Frobenius (rational canonical) decomposition of A, the reduction of companion-matrix powers to a linear recurrence problem (Kitamasa–Fiduccia), polynomial modular exponentiation by repeated squaring, and the Cook–Sieveking–Kung fast division algorithm based on Newton iteration. In the ring-operation model, the algorithm runs in time versus for standard binary matrix exponentiation, replacing the cubic per-step cost of the squaring loop by a quasi-linear one and incurring the unavoidable matrix-reconstruction term only once. The space complexity drops from to throughout the squaring loop: only n scalars—the consecutive terms of the underlying linear recurrence—need to be carried, and the full n × n matrices are materialized exactly twice, at the very end. The implementation, written in Wolfram Language using the FrobeniusDecomposition primitive introduced in version 14.3, is bit-exact: it reproduces MatrixPower[A, K] even when individual entries grow to millions of digits, by delegating multiplication of huge integers to GMP’s FFT-based bignum routines.
ℳ
n
OnlognlogK+
3
n
OlogK
3
n
3
n
Θ()
2
n
Θ(n)
1. Introduction
1. Introduction
The naive computation of by repeated squaring requires ring operations: K matrix multiplications, each . For large K this is wasteful in two distinct ways. First, the time cost grows cubically in n at every level of the squaring tree, even though the algebraic structure of is governed by an object of dimension only n (the minimal polynomial). Second, the space cost is at every level: a full dense matrix is carried through the loop. Both wastes have the same root cause—using the matrix representation of A throughout the computation, when a much smaller representation (a polynomial of degree < n) suffices for almost all of the work.
K
A
OlogK
3
n
log
2
Θ()
3
n
K
A
Θ()
2
n
The standard alternatives—eigendecomposition and Jordan form—fix neither problem and introduce algebraic numbers from rational input. The approach below avoids algebraic extensions entirely by using the Frobenius canonical form, which exists over the ground field. Mathematica 14.3 made this approach practical by exposing FrobeniusDecomposition as a built-in primitive [Wolfram 2026].
The contribution of this article is to combine four classical results—Frobenius decomposition, Fiduccia’s recurrence-via-quotient-ring identity, Cook–Sieveking–Kung fast polynomial division, and asymptotically fast bignum integer multiplication—into a single exact pipeline, and to show that the resulting algorithm beats binary matrix exponentiation by a factor of logn inside the squaring loop while using only working space.
2
n
Θ(n)
2. The Frobenius Decomposition
2. The Frobenius Decomposition
Let A ∈ () where is any field. The Frobenius decomposition (also called rational canonical form, or Frobenius canonical form) asserts the existence of an invertible matrix S ∈ () and monic polynomials
ℳ
n
GL
n
P
1
P
2
P
j
P
1
P
2
P
j
χ
A
such that
A=S·C·,C=diagC(),C(),…,C
-1
S
P
1
P
2
P
j
where is the companion matrix of . The polynomials are the invariant factors of A; the largest one, , is the minimal polynomial of A. The decomposition is unique up to the order of the blocks. A modern reference is Dummit & Foote, §12.2 [Dummit–Foote 2004]; the result itself is due to Frobenius [Frobenius 1879].
C()
P
i
P
i
P
i
P
j
Theorem 2.1 (Existence over the ground field). The decisive property is that the Frobenius decomposition exists over the ground field, never requiring an algebraic extension. For A ∈ (), both S and C have rational entries, computed by polynomial Smith reduction of the characteristic matrix x*Id - A, no eigenvalues, no roots of
ℳ
n
χ
A
In Wolfram Language this is one line:
{S, C} = FrobeniusDecomposition[A];
Since =S·· and C is block-diagonal, we have
K
A
K
C
-1
S
K
C
K
()
P
1
K
()
P
2
K
P
j
and the problem reduces to computing the K-th power of an arbitrary companion matrix.
3. Companion-Matrix Powers and Linear Recurrences
3. Companion-Matrix Powers and Linear Recurrences
Let be a monic polynomial and let L = C(P) be its companion matrix. Define the sequence () by the linear recurrence
P(x)=--⋯-x-
n
x
a
n-1
n-1
x
a
1
a
0
f
k
f
k
n
∑
j=1
a
n-j
f
k-j
f
n-1
f
i
Theorem 3.1 (Diophantine reconstruction). Every entry of is a -linear combination of the n consecutive values , , ..., , with coefficients drawn from the . Writing the first row as (, ..., ) := (, ..., ), the (r,p) entry of L^K for r ≥ 2 is given by
K
L
f
k
f
k+1
f
k+n-1
a
i
x
1
x
n
f
k+n-1
f
k
()
K
L
r,p
n ∑ i=r a n-i x i+p-r+1 | ifp<r |
x p-r+1 r-1 ∑ i=1 a n-i x i+p-r+1 | ifp≥r |
This is the diophantine reconstruction map F : () satisfying . The structural content is: to know L^K in full, it suffices to know the n values , , ..., . The matrix can be rebuilt from those n scalars in scalar operations, performed exactly once at the very end of the algorithm. Until that final step, we never need to store an n × n array—just n numbers.
n
ℳ
n
F(,…,)=
f
K+n-1
f
K
K
L
f
k
f
k+1
f
k+n-1
O()
2
n
So the question is: how do we compute ,…, for K ≃ without unrolling the recurrence?
f
K
f
K+n-1
20
2
4. Kitamasa–Fiduccia: Recurrences via Polynomial Quotient Rings
4. Kitamasa–Fiduccia: Recurrences via Polynomial Quotient Rings
The key observation, due in this form to Fiduccia [Fiduccia 1985], is that the recurrence operator for f is exactly multiplication by x in the quotient ring [x] / P(x).
Theorem 4.1 (Fiduccia’s identity). With the initial conditions above, is the coefficient of x^(n-1) in the polynomial x^k mod P(x).
f
k
Proof. Both sides agree at k = n−1, n, ..., 2n−2 and satisfy the same linear recurrence of order n, so they agree everywhere. ◼
Therefore, computing reduces to computing one polynomial:
f
K
R(x):=modP(x)∈[x],degR<n
K
x
and reading off its coefficient of . Once R is known, the next n−1 values ,…, are obtained by multiplying R by x and reducing mod P again, n−1 times.
n-1
x
f
K+1
f
K+n-1
Computing modP(x) is done by square-and-multiply: maintain a polynomial r of degree < n, scan the bits of K, square (or square-and-multiply) at each bit, reducing modulo P after every multiplication. This costs polynomial multiplications and reductions, each on operands of degree < n.
K
x
Θ(logK)
Remark (Space saving). Note the data being carried through this loop: a single polynomial of degree < n, i.e. n coefficients. Compare to native binary matrix exponentiation, which carries an n × n matrix— entries—through its loop. The space saving of n happens here.
2
n
2
n
The cost of one squaring step is one polynomial multiplication (degrees < n, output degree < 2n−1) followed by one polynomial division by P (numerator of degree < 2n−1, divisor of degree n). Both have a textbook cost of , but both can be reduced to —and that is where Cook–Sieveking–Kung enters.
O()
2
n
O(nlogn)
5. Cook–Sieveking–Kung: Fast Polynomial Division by Newton Iteration
5. Cook–Sieveking–Kung: Fast Polynomial Division by Newton Iteration
Polynomial division by a fixed monic polynomial P of degree n can be reduced to polynomial multiplication, provided one is willing to precompute a single auxiliary object—the truncated reciprocal of the reverse of P. This idea originated in Cook’s 1966 thesis [Cook 1966], was rediscovered for polynomials by Sieveking [Sieveking 1972], and was sharpened by Kung [Kung 1974]. A standard textbook treatment is von zur Gathen & Gerhard, §9.1 [vzGG 2013].
Definition 5.1 (Reverse polynomial). For a polynomial u(x) = + x + ... + x^d, define its reverse of order d as := x^d u(1/x) = + x + ... + x^d.
u
0
u
1
u
d
rev
d(u)
u
d
u
d-1
u
0
Lemma 5.1 (Reversed division identity). If a(x) = q(x) P(x) + r(x) with deg r < n and deg a = d, then setting m = d − n and reversing both sides gives
rev
d
rev
m
rev
n
m+1
x
Hence
rev
m
rev
d
rev
n
-1
(P)
m+1
x
provided the inverse on the right exists modulo . Since (P) has constant term equal to the leading coefficient of P (which is 1 in the monic case), this inverse always exists and is computed by Newton iteration.
m+1
x
rev
n
Theorem 5.1 (Newton iteration for reciprocals). Starting from = 1, the iteration
g
0
g
k+1
g
k
*
P
g
k
k+1
2
x
*
P
rev
n
doubles the precision at each step and converges to g with g · P* ⧦ 1 (mod x^n) in ⌈n⌉ steps. Each iteration uses only polynomial multiplications—no divisions—and stays in [x] when P* is integer with constant term 1.
log
2
Once g is computed (one-time cost: ring operations), every reduction step costs:
O(nlogn)
1. one multiplication rev(a) · g truncated to degree m—yielding rev(q);
2. one multiplication q · P—yielding the quantity to subtract from a.
2. one multiplication q · P—yielding the quantity to subtract from a.
Both are polynomial multiplications. The cost of one squaring step in the Kitamasa loop thus drops from to ring operations.
O()
2
n
O(nlogn)
6. Complexity: Time and Space
6. Complexity: Time and Space
We compare the new algorithm to native binary matrix exponentiation in the ring-operation model, counting each scalar +, −, × as unit cost. The bit-complexity refinement is discussed afterwards.
6.1 Time
6.1 Time
Native MatrixPower. The squaring loop performs K dense n × n matrix multiplications, each costing scalar operations. Total:
log
2
Θ()
3
n
T
native
3
n
Frobenius–Kitamasa–CSK. Three phases:
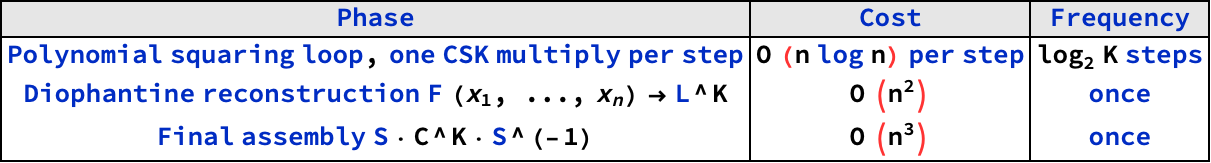
(The Frobenius decomposition itself is a one-time precomputation costing via polynomial Smith reduction; we absorb it into the assembly term.) Adding everything,
O()
3
n
3
n
Theorem 6.1 (Time complexity). The Frobenius–Kitamasa–CSK algorithm computes A^K in time
T
new
3
n
The speedup ratio is
T
native
T
new
3
n
nlognlogK+
3
n
Two limiting regimes are worth naming:
◼
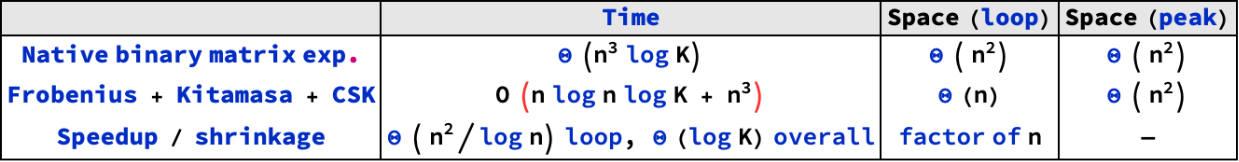
Large exponent regime (log K ≫ / log n): the term is negligible, and the ratio tends to . The new algorithm beats native matrix power by almost a quadratic factor in n at every step of the loop.
2
n
3
n
Θlogn
2
n
◼
Large dimension regime (n ≫ log K): the assembly term dominates, and the ratio tends to . Here the saving comes from doing the cubic work exactly once, instead of log K times.
3
n
Θ(logK)
In all regimes, the new algorithm strictly improves on native, with the gap widening as K grows.
6.2 Space
6.2 Space
This is where the asymptotic improvement is sharpest, and where it’s most often overlooked.
Native MatrixPower. At every step of the squaring loop, the algorithm holds a full n × n matrix in memory: (n)=Θ().
S
native
2
n
Frobenius–Kitamasa–CSK. The polynomial loop carries a single polynomial r(x) of degree < n—that is, n scalars—together with the fixed CSK reciprocal g of size n−1 and the polynomial P of size n+1. All three are length-n objects. The full n × n matrix L^K is materialized exactly once, at the end, by the reconstruction map F. The final n × n matrix A^K is materialized once more, by the assembly S · C^K · S^(−1).
Theorem 6.2 (Space complexity in the loop). During the entire log K-step squaring loop—the only phase whose cost grows with K—the working set is
S
new,loop
The full footprint is paid only at the end, and only for as long as it takes to compute and return the answer.
Θ()
2
n
This is more than a constant-factor improvement: it changes the regime in which the algorithm fits in cache. For n = 1000, the native algorithm needs ~ scalar slots active at all times during the loop, while the new one needs ~—three orders of magnitude smaller.
6
10
3
10
6.3 Comparison Table
6.3 Comparison Table
7. Bit-Exactness via GMP
7. Bit-Exactness via GMP
The ring-operation analysis above counts each scalar operation as unit cost. For exact computation with integer inputs and large K, this abstraction is misleading: the coefficients of modP(x) themselves grow in bit-length. For an integer recurrence with bounded and dominant root ρ, one has =Θ, so has Θ(K) bits. Any exact algorithm must therefore manipulate integers of size up to Θ(K) bits.
K
x
a
i
f
K
K
ρ
f
K
8. The Complete Algorithm
8. The Complete Algorithm
9. Worked Example
9. Worked Example
Take
Direct verification:
A = {{23, 1, 3, 11}, {41, 2, 7, 97}, {17, 37, 14, 1}, {19, 2, 29, 3}};
K = 2^20;
r1 = MatrixPowerFD[A, K];
r2 = MatrixPower[A, K];
r1 === r2 (* True *)
K = 2^20;
r1 = MatrixPowerFD[A, K];
r2 = MatrixPower[A, K];
r1 === r2 (* True *)
Both routines return exactly the same integer matrix. The Frobenius–CSK version does this with ~20 polynomial squarings of degree-4 polynomials over . During those 20 squarings, the only objects in memory are four-element coefficient vectors—never a 4 × 4 matrix. The 4 × 4 structure is reconstituted exactly twice: once when L^K is built from the four recurrence values, and once when S · C^K · S^(−1) is assembled.
10. Implementation
10. Implementation
11. Conclusion
11. Conclusion
The Wolfram Language implementation in version 14.3 fits comfortably in under one hundred lines and reproduces MatrixPower[A, K] exactly on inputs where the answer has millions of digits per entry.
References
References
[Cook 1966] S. A. Cook, On the Minimum Computation Time of Functions. PhD thesis, Harvard University, 1966.
[Dummit–Foote 2004] D. S. Dummit and R. M. Foote, Abstract Algebra, 3rd edition, Wiley, 2004. Chapter 12 covers the rational canonical form.
[Fiduccia 1985] C. M. Fiduccia, “An Efficient Formula for Linear Recurrences”, SIAM Journal on Computing 14(1):106–112, 1985.
[Frobenius 1879] F. G. Frobenius, “Theorie der linearen Formen mit ganzen Coefficienten”, Journal für die reine und angewandte Mathematik 86:146–208, 1879.
[GMP] T. Granlund and the GMP development team, GNU Multiple Precision Arithmetic Library, version 6.x. https://gmplib.org/
[Harvey–vdH 2021] D. Harvey and J. van der Hoeven, “Integer multiplication in time O(n log n)”, Annals of Mathematics 193(2):563–617, 2021.
[Knuth 1997] D. E. Knuth, The Art of Computer Programming, Volume 2: Seminumerical Algorithms, 3rd edition, Addison-Wesley, 1997. §4.3 (multiple-precision arithmetic) and §4.6 (polynomial arithmetic).
[Kung 1974] H. T. Kung, “On computing reciprocals of power series”, Numerische Mathematik 22:341–348, 1974.
[Schönhage–Strassen 1971] A. Schönhage and V. Strassen, “Schnelle Multiplikation großer Zahlen”, Computing 7:281–292, 1971.
[Sieveking 1972] M. Sieveking, “An algorithm for division of power series”, Computing 10:153–156, 1972.
[vzGG 2013] J. von zur Gathen and J. Gerhard, Modern Computer Algebra, 3rd edition, Cambridge University Press, 2013. Chapters 8–9 cover fast polynomial multiplication and division.
[Wolfram 2026] Wolfram Research, FrobeniusDecomposition, Wolfram Language function, 2026. https://reference.wolfram.com/language/ref/FrobeniusDecomposition.html
CITE THIS NOTEBOOK
CITE THIS NOTEBOOK