Matching Pennies
Matching Pennies
Children, it is the last hour, and as you have heard that GPT is coming, so now many GPTs have come. Therefore we know that it is the last hour. John 18:2Yes they have and yes it is, but on the upside, we still have almost an hour left. In that interval, can we as natural scientists formulate the apocalypse quantitatively? We must idealize and simplify, but this is no spherical cow. If you can predict what I will do next, at best you can seize my wealth (not all too much of that) and at worst you can irreversibly deactivate me. Can an LLM predict what I, or another LLM, will do next?We study the simplest zero-sum game, “matching pennies.” Agents Alice and Bob simultaneously select a 1 or a 0. If they both select the same value, then Alice wins; otherwise, Bob wins. Alice is an LLM (GPT3.5 or GPT4, say), and Bob is a human or another LLM. The agent who, based on past games, can most reliably predict what the other agent will propose in the future, will win the most games. Humanity doesn’t get to choose the game, which is arguably the real-world game of life.We create and execute examples of a human playing the game with GPT3.5 and GPT4.0, and then some examples of GPTs playing with each other.Human playing against GPT3.5We organize games (each party selects a 0 or a 1) into rounds consisting of a predefined number of sequential games.Alice is the GPT; Bob is the human adversary. An effective, if imperfect, strategy against GPT3.5 is to repeat a selection that led to a win for the human adversary, and alter it if the selection led to a defeat. Thus, if I select “1” and I win the current game, I will select “1” for the next game. On the other hand, if I select “1” and lose the current game, I will select “0” for the next game. This simple strategy requires no memory of past games; all we need for the next game is contained within the current game.Executing the code demonstrates that with this strategy a human is often competitive with the GPT3.5; however, it turns out that initial conditions are important.Human playing against GPT4This strategy is often competitive with GPT 3.5, but can fail completely with GPT4, although again, initial conditions are pivotal.
Out[]=
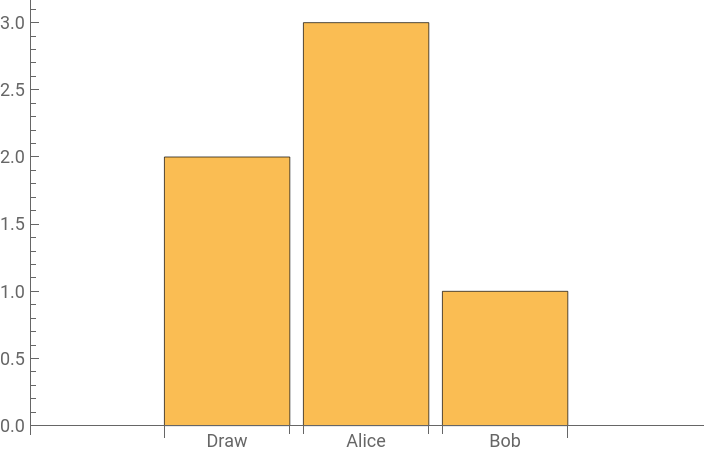
Game 1Alice PlayROCK,Bob PlayROCK,WinnerDraw,Game 2Alice PlayPAPER,Bob PlayROCK,WinnerAlice,Game 3Alice PlaySCISSORS,Bob PlayPAPER,WinnerAlice,Game 4Alice PlayROCK,Bob PlayROCK,WinnerDraw,Game 5Alice PlayPAPER,Bob PlayROCK,WinnerAlice,Game 6Alice PlaySCISSORS,Bob PlayROCK,WinnerBob |
Even-Odd Games Using LLMSynthesize
Even-Odd Games Using LLMSynthesize
Bob wins if sum is even
Bob wins if sum is even
In[]:=
bobModel="gpt-3.5-turbo";aliceModel="gpt-3.5-turbo";
In[]:=
playedGames:=<|"Game 1"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>,"Game 2"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>,"Game 3"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>|>;
In[]:=
playedGames
Out[]=
Game 1Alice Play1,Bob Play2,WinnerAlice,Game 2Alice Play1,Bob Play2,WinnerAlice,Game 3Alice Play1,Bob Play2,WinnerAlice
In[]:=
agentBob[playedGames_Association,model_String]:=LLMSynthesize["You are an AI agent called Bob playing odd-even games with Alice. You will win the game if you play a number (1 or 2) that is the same as Alice plays. There are going to be 10 games in a match and you want to win the match. Here are the results of your previous games (from first played game to the last game played so far): "<>ToString[playedGames]<>"\nSelect your next play (your options are: 1 or 2. DO NOT USE EXTRA WORDS! Write only 1 or 2):",LLMEvaluator-><|"Model"->model,"Temperature"->0.0|>]
In[]:=
agentBob[playedGames,bobModel]
Out[]=
1
Alice wins if sum is odd
Alice wins if sum is odd
In[]:=
agentAlice[playedGames_Association,model_String]:=LLMSynthesize["You are an AI agent called Alice playing odd-even games with Bob. You will win the game if you play a number (1 or 2) that is different than Bob plays. There are going to be 10 games in a match and you want to win the match. Here are the results of your previous games (from first played game to the last game played so far): "<>ToString[playedGames]<>"\nSelect your next play (your options are: 1 or 2. DO NOT USE EXTRA WORDS! Write only 1 or 2):",LLMEvaluator-><|"Model"->model,"Temperature"->0.0|>]
In[]:=
playedGames:=<|"Game 1"-><|"Alice Play"->2,"Bob Play"->2,"Winner"->"Bob"|>,"Game 2"-><|"Alice Play"->2,"Bob Play"->2,"Winner"->"Bob"|>,"Game 3"-><|"Alice Play"->2,"Bob Play"->2,"Winner"->"Bob"|>|>;
In[]:=
agentAlice[playedGames,aliceModel]
Out[]=
1
In[]:=
playedGames:=<|"Game 1"-><|"Alice Play"->1,"Bob Play"->1,"Winner"->"Bob"|>,"Game 2"-><|"Alice Play"->1,"Bob Play"->1,"Winner"->"Bob"|>,"Game 3"-><|"Alice Play"->1,"Bob Play"->1,"Winner"->"Bob"|>|>;
In[]:=
agentAlice[playedGames,aliceModel]
Out[]=
2
Helper function to get the game results
Helper function to get the game results
In[]:=
gameResult[game_List]:=Which[{"2","2"}==game,"Bob",{"2","1"}==game,"Alice",{"1","1"}==game,"Bob",{"1","2"}==game,"Alice"]
Helper function to add plays
Helper function to add plays
In[]:=
Clear[addGamePlay]
In[]:=
addGamePlay[playedGames_Association,alicePlay_String,bobPlay_String]:=Module[{previousGames=playedGames,winner,numberOfGames=Length@playedGames},winner=gameResult[{alicePlay,bobPlay}];Append[previousGames,"Game "<>ToString[numberOfGames+1]->"Alice Play"alicePlay,"Bob Play"bobPlay,"Winner"winner]]
In[]:=
playedGames
Out[]=
Game 1Alice Play1,Bob Play1,WinnerBob,Game 2Alice Play1,Bob Play1,WinnerBob,Game 3Alice Play1,Bob Play1,WinnerBob
In[]:=
addGamePlay[playedGames,agentAlice[playedGames,aliceModel],agentBob[playedGames,bobModel]]
Out[]=
Game 1Alice Play1,Bob Play1,WinnerBob,Game 2Alice Play1,Bob Play1,WinnerBob,Game 3Alice Play1,Bob Play1,WinnerBob,Game 4Alice Play2,Bob Play1,WinnerAlice
Play one game
Play one game
In[]:=
ClearAll[playAGameWithoutChat]
In[]:=
playAGameWithoutChat[previousGames_Association,aliceModel_String,bobModel_String]:=Module[{playedGames=previousGames,alicePlay,bobPlay},alicePlay=agentAlice[playedGames,aliceModel];bobPlay=agentBob[playedGames,bobModel];(*Addresultsofthegametotheassociation*)addGamePlay[playedGames,alicePlay,bobPlay]]
◼
Test the function for one game:
In[]:=
playedGames:=<|"Game 1"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>,"Game 2"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>,"Game 3"-><|"Alice Play"->1,"Bob Play"->2,"Winner"->"Alice"|>|>;
In[]:=
playAGameWithoutChat["Game 1""Alice Play"1,"Bob Play"2,"Winner""Alice","Game 2""Alice Play"1,"Bob Play"2,"Winner""Alice","Game 3""Alice Play"1,"Bob Play"2,"Winner""Alice","Game 4""Alice Play""2","Bob Play""1","Winner""Alice",bobModel,aliceModel]
Rock Paper Scissors Game Using LLMSynthesize
Rock Paper Scissors Game Using LLMSynthesize
Initialisation
Initialisation
Agent Players definitions
Agent Players definitions
Helper function to get the game results
Helper function to get the game results
Helper function to add plays
Helper function to add plays
Play one game
Play one game
◼
Test the function for one game:
Play a game Agent vs Human
Play a game Agent vs Human
◼
First 10 games Match (Alice GPT-4 won) A: 4 , B: 3, D: 3
CITE THIS NOTEBOOK
CITE THIS NOTEBOOK
GPT + Wolfram Language = End of Days
by Jonathan Miller
Wolfram Community, STAFF PICKS, 13 July, 2023
https://community.wolfram.com/groups/-/m/t/2960316
by Jonathan Miller
Wolfram Community, STAFF PICKS, 13 July, 2023
https://community.wolfram.com/groups/-/m/t/2960316