I built AI driven semantic search of Stephen Wolfram’s Science and Technology for Kids (and Adults) Q&A and deployed it to Wolfram Cloud as an application:
Content is taken from the YouTube auto-generated transcription, chunking it up and then using the Embedding API to find the top 3 most relevant to the question.
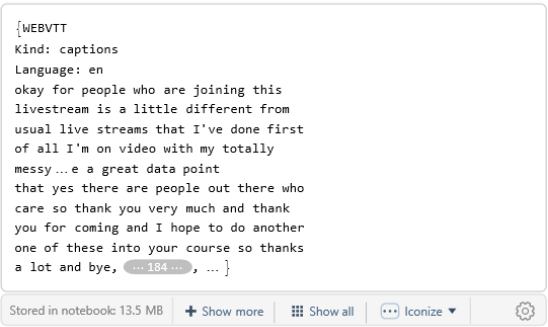
YouTube has already transcribed the videos Stephen Wolfram has been posting. I used a YouTube Downloader to download these transcripts. (Other podcasts I would have used the OpenAI Whisper API to go from voice to text). I actually asked chatGPT to write small python scripts to help further process the text from .VTT format to plain text. (doit.py is available upon request)
I imported all transcript. Saved it in the notebook itself. It’s only 13.5 MB
In[]:=
txtFiles=FileNames["*.txt","D:\\yt-dlp\\wolfram"];
In[]:=
allTranscript=Import/@txtFiles
Out[]=
In[]:=
import tiktokendef tokenize_text(text): enc = tiktoken.get_encoding("cl100k_base") return enc.encode(text)
Out[]=
ExternalFunction

In[]:=
tokenizeText=ExternalFunction
Out[]=
ExternalFunction
In[]:=
tokenizeText[First[allTranscript]]//Length
Out[]=
46955
In[]:=
TextSentences[First[allTranscript]]//Length
Out[]=
1
In[]:=
StringSplit[First[allTranscript],"\n"]//Length
Out[]=
5290
I split it into chunks. I had a look at OpenAI’s Retrieval plugin for how they do it.
In[]:=
chunks=Flatten[Map[StringRiffle,Partition[StringSplit[#,"\n"],UpTo[128],125]]&/@allTranscript]
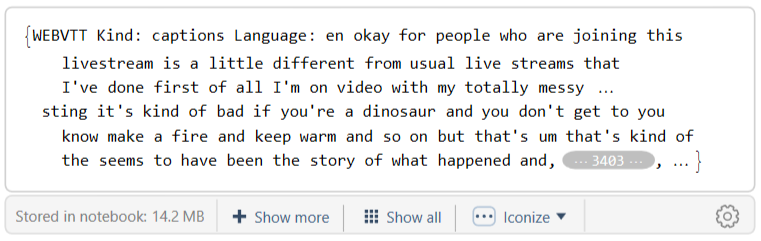
I checked the number of tokens to see what the longest chunk is, to make sure I am not exceeding the limit. It looked okay.
In[]:=
MinMax[Length[tokenizeText[#]]&/@chunks]
Out[]=
{6,1171}
In[]:=
chunks//Length
Out[]=
3405
I used Christopher Wolfram’s OpenAILink to work with the OpenAI API.
In[]:=
Needs["ChristopherWolfram`OpenAILink`"]
$OpenAIKey=Missing[];
I embedded the chunks of text.
In[]:=
embeddings=ParallelMap[OpenAIEmbedding,chunks]
The main functionality then embeds the question, find similar embedded transcription chunks using Nearest[] and then feeds the top 3 chunks along with the question to OpenAI chat completion for an answer.
In[]:=
askWolfram[question_String]:=Module[{questionEmbedding,chunkNdx,answer},questionEmbedding=OpenAIEmbedding[question];chunkNdx=Nearest[embeddings->"Index",questionEmbedding,3];answer=OpenAIChatComplete[{OpenAIChatMessageObject["system","Please answer the question using what you know and what you learn from the three transcription chunks provided. All transcriptions are taken from the \"Science and Technology Q&A for Kids and Adults\" where Stephen Wolfram hosts a live and unscripted Ask Me Anything about the history of science and technology for all ages."],OpenAIChatMessageObject["user","Transcriptions chunks: "<>StringRiffle[chunks[[chunkNdx]],"\n\n---\n\n"]],OpenAIChatMessageObject["user","Question: "<>question]}];Return[Panel[Column[List[Style[answer["Text"],Bold,Larger]]]]]]
In[]:=
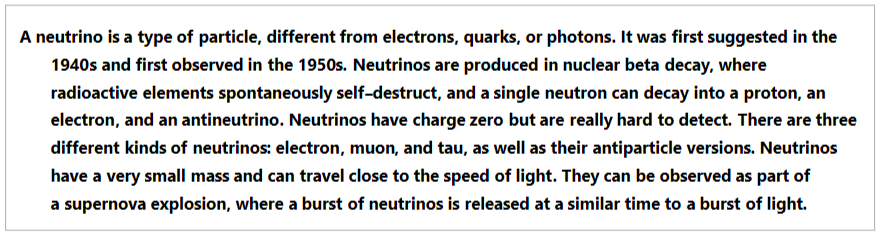
askWolfram["What is a neutrino?"]
Deploying in a FormPage[]
In[]:=
CloudDeploy[FormPage["question"->String,askWolfram[#question]&,AppearanceRules-><|"Title"->"ask Stephen Wolfram","Description"->Hyperlink["Using the Science and Technology for Kids (and Adults) Videos from YouTube","https://www.youtube.com/playlist?list=PLxn-kpJHbPx2KE5Fkwvkau-ME2yz0nDkF"]|>],AutoRemove->False,Permissions->"Public"]
Out[]=
CITE THIS NOTEBOOK
CITE THIS NOTEBOOK
AI driven semantic search, ask Stephen Wolfram anything
by Tamas Simon
Wolfram Community, STAFF PICKS, April 26, 2023
https://community.wolfram.com/groups/-/m/t/2907831
by Tamas Simon
Wolfram Community, STAFF PICKS, April 26, 2023
https://community.wolfram.com/groups/-/m/t/2907831