Setting the Stage: How This Notebook Flows
Setting the Stage: How This Notebook Flows
This notebook is a computation-first tour of the single qubit, how a two-dimensional Hilbert space description (kets, bras, inner products) turns into the geometric Bloch ball, how measurements (Born rule, eigenbases, projectors) read probabilities directly from amplitudes, why density matrices are required to describe ensembles and mixedness (purity, von Neumann entropy), and how unitary dynamics and spinors live in SU(2) while their visible action on the Bloch vector is an SO(3) rotation. Along the way, we build the Pauli operator toolkit explicitly, Hermiticity, commutators/anticommutators, Levi–Civita structure, Pauli product identities, closed-form exponentials, dynamical equation, collapse of the state during measurment and more, so that every abstract statement is immediately testable computationally and every result can be interpreted both algebraically and geometrically.
In other words, I’ve tried to build a catalogue of computational experiments on single qubits, tools and examples that help you run experiments computationally and learn directly from what you observe. I strongly believe in a computation-first narrative for learning: in a sense, if I cannot compute it, I cannot claim to understand it. This echoes a very Feynman-y idea: real understanding shows up when you can do the thing, derive it, predict it, simulate it, estimate it, rather than just repeat/read words.
Before we start, pay attention to a few things. The environment you see is a Wolfram (Mathematica) notebook. Wolfram notebooks consist of sequences of cells. Look at the right side of this notebook and you can see cell brakets. This notebook is written so that you should evaluate the cells from top to bottom. Although I did my best to make the input cells independent, there are still variables that are defined in earlier cells and used later, meaning some cells depend on previous ones. You should be mindful of these dependencies when evaluating the notebook.
Additionally, the story is presented as a continuous sequence, like a movie. I have added a few headings to help with transitions from one topic to another, but I have avoided breaking the narrative into rigid sections. Sometimes a feature or property is introduced and used before we explain why it applies or unpack the underlying mathematical details. This is intentional, because in this notebook the ability to apply an idea often matters more than following an abstract proof first. Overall, the rhythm is: concept → computation → interpretation.
Inevitably, some of the code in this notebook will look complicated at first. My suggestion is to focus on the output and its meaning before worrying about every detail of the input code. Once you understand what a piece of code is doing conceptually, then go back and unpack how it is written.
Remember that you are not locked into the code as given. You can (and should) modify it, try your own variations, and run your own numerical experiments. Almost every line in this notebook could be written in several different ways, and exploring those alternatives is one of the best ways to learn.
One of the strengths of the Wolfram Mathematica notebook environment is precisely this interactive, exploratory style. If you are using the cloud version, you can click “Make Your Own Copy” to duplicate the notebook and edit it freely. If you are working locally, save your own version and experiment with it. The notebook interface is a powerful medium for computational thinking and simulation; it is worth taking the time to get comfortable with it and really use it as a laboratory for your ideas.
If you have any suggestions or questions, please reach out to us at quantum@wolfram.com
Let’s start!
Complex Numbers as Two Degrees of Freedom
Complex Numbers as Two Degrees of Freedom
The simplest quantum system we usually consider in quantum mechanics is one whose states live in a two-dimensional Hilbert space, what we call a single qubit. A Hilbert space is a complex vector space equipped with an inner product, and it is complete with respect to the norm induced by that inner product. In such a two-dimensional Hilbert space, the state of the system may be represented in two equivalent-looking but conceptually distinct ways: for an isolated system in a definite pure state, we use a normalized state vector (a two component complex vector); more generally—especially when describing classical uncertainty about preparation, entanglement with an environment, or partial information, we use a density operator/matrix (a 2×2 matrix), which acts on the same Hilbert space and provides the most general description of a qubit’s state. Whether we represent the qubit by a state vector or by a density matrix, the underlying objects are built from complex numbers.
A complex number can be written as , where and are real numbers and is the imaginary unit, defined by =-1. The same number can also be written in polar form as , where is the absolute value (modulus) of , and φ is its argument (angle). The complex conjugate of , denoted by , is given by =x-y, or equivalently in polar form. In short, a complex number contains two real degrees of freedom.
z=x+y
x
y
2
z=r
φ
r=z
z
z
*
z
*
z
z=r
-φ
Compute the complex conjugate of :
3+2
In[]:=
Conjugate[3+2]
Out[]=
3-2
Find in polar form:
3+2
In[]:=
AbsArg[3+2]
Out[]=
13
,ArcTan2
3
Verify that the polar form is the same as the original complex number:
In[]:=
#1&@@AbsArg[3+2]==3+2
#2
Out[]=
True
As said, the complex number has two degrees of freedom: . Using them, one can construct the polar form of the complex number.
3+2
{3,2}
In[]:=
ToPolarCoordinates[{3,2}]
Out[]=
13
,ArcTan2
3
Multiplication of a complex number by its complex conjugate is always a non-negative real number. This product is written as z or , and is usually denoted by the absolute square . Given the polar form, one can write =. The usual norm of (also called the modulus) is .
*
z
z
*
z
2
z
2
z
2
r
z
z=z=r
State Vectors and Normalization (Norms, Global Phase, Degrees of Freedom)
State Vectors and Normalization (Norms, Global Phase, Degrees of Freedom)
For a two-level quantum system (qubit), a pure state is represented (up to an overall complex phase such as ) by a two-component complex vector, usually called the state vector. For example, the vector represents a pure quantum state. We will assume that all state vectors are normalized, meaning that their norm is equal to 1. For a vector with components and , i.e. ={,} , the norm is defined as , where * denotes the complex conjugate and “·” denotes the usual dot product. The complex conjugate of a vector is obtained by taking the complex conjugate of each of its components.
φ
,
1
2
3
2
v
v
0
v
1
v
v
0
v
1
||||=.=+
v
*
v
v
2
v
0
2
v
1
Calculate the complex conjugate of :
,
1
2
3
2
In[]:=
Conjugate1,
3
2Out[]=
,-
1
2
3
2
Calculate norm of :
,
1
2
3
2
In[]:=
Norm1,
3
2Out[]=
1
Calculate norm of explicitly as .v:
,
1
2
3
2
*
v
In[]:=
Withvector=1,
3
2,Conjugate[vector].vector
Out[]=
1
Calculate norm of :
{Cos[θ/2],Sin[θ/2]}
ϕ
In[]:=
FullSimplifyNormCos[θ/2],Sin[θ/2],(θ|ϕ)∈Reals
ϕ
Out[]=
1
Calculate norm of the state vector :
{α,β}
In[]:=
Norm[{α,β}]
Out[]=
2
Abs[α]
2
Abs[β]
Since the norm of a state vector is not automatically equal to one, we often multiply the vector by an overall (nonzero) scalar factor, typically called a normalization factor, to ensure the state is normalized.
Normalize the state vector :
{α,β}
In[]:=
Normalize[{α,β}]
Out[]=
+,+
α
2
Abs[α]
2
Abs[β]
β
2
Abs[α]
2
Abs[β]
In the above example, + is the normalization factor.
1
2
Abs[α]
2
Abs[β]
Verify the norm is now 1:
In[]:=
Norm@Normalize[{α,β}]//FullSimplify
Out[]=
1
As mentioned before, for a qubit, the state vector is represented by a two-component complex-valued vector, for example . The numbers and are called (probability) amplitudes. They are the coefficients of the basis states in the linear combination that describes the quantum superposition.
{,}∈
c
1
c
2
2
c
1
c
2
Multiplying a state vector by an overall complex phase factor does not change the physical quantum state it represents, because all physical predictions (for example, measurement probabilities, which depend on absolute squares of amplitudes ) are unchanged by a global phase.
φ
2
c
j
Compute probabilities and verify two states and {α,β} are physically the same:
{α,β}
φ
In[]:=
FullSimplify==,φ∈Reals
2
Abs[{α,β}]
2
Abs{α,β}
φ
Out[]=
True
We will discuss measurement probabilities in more detail later.
The Most General Pure Qubit State
The Most General Pure Qubit State
When we want to write a general pure state of a single qubit, we can choose a global phase so that the first component of the state vector is real (as if in the polar form, we set its argument as zero), while the second component may be complex. If we also require the state to be normalized, the most general pure qubit state can be written as where and . We will discuss the motivation to have rather than soon when we introduce Bloch sphere. Let’s rephrase this idea differently.
{Cos[θ/2],Sin[θ/2]}
ϕ
0<=θ<=π
0<=ϕ<=2π
θ/2
θ
The state vector of a single qubit can be written as with . This means the state is specified by two complex numbers, i.e., four real parameters, i.e. . Imposing normalization, removes one real degree of freedom, and identifying state vectors that differ only by an overall complex phase removes another real degree of freedom. Mathematically it means: . Therefore, a pure qubit state is fully characterized by only two real parameters.
{α,β}
α,β∈
,
r
0
φ
0
r
1
φ
1
,->+,->+,->r,
r
0
φ
0
r
1
φ
1
1
2
r
0
2
r
1
r
0
φ
0
r
1
φ
1
φ
0
2
r
0
2
r
1
r
0
r
1
(-)
φ
1
φ
0
1-
2
r
φ
Bra–Ket Notation and Inner Products
Bra–Ket Notation and Inner Products
In the quantum mechanics literature, a state vector is usually denoted by a ket. For example, can represent a generic pure state such as . The Hermitian conjugate (complex conjugate transpose) of a ket is denoted by a bra. For the state above, the corresponding bra is . The inner product of two states and is written as , which means the dot product of the bra with the ket |ψ₂⟩.
|ψ〉
|ψ〉={Cos[θ/2],Sin[θ/2]}
ϕ
〈ψ|={Cos[θ/2],Sin[θ/2]}
-ϕ
|〉
ψ
1
|〉
ψ
2
〈|〉
ψ
1
ψ
2
〈|
ψ
1
Define and :
|〉
ψ
1
|〉
ψ
2
In[]:=
ψ1=Cos[θ1/2],Sin[θ1/2];ψ2=Cos[θ2/2],Sin[θ2/2];
ϕ1
ϕ2
Calculate their inner product:
In[]:=
FullSimplify[Conjugate[ψ1].ψ2,(θ1|θ2|ϕ1|ϕ2)∈Reals]
Out[]=
CosCos+SinSin
θ1
2
θ2
2
(-ϕ1+ϕ2)
θ1
2
θ2
2
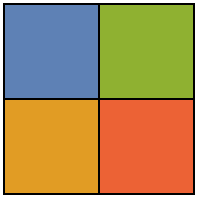
Note that Mathematica does not force the “row vs. column” distinction for rank-1 lists (what we usually call vectors) in the same way introductory linear algebra does. A vector is represented as a single list, rather than explicitly as a row matrix or an column matrix. As a result, Transpose has no visible effect on a vector (a 1D list), while it does change a matrix (a 2D list) by swapping rows and columns.
1×n
n×1
Visualize the transposition on a vector as described in linear algebra:
Out[]=
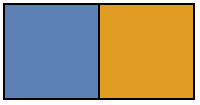
Transpose
⟶
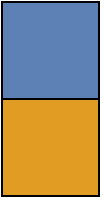
Visualize the transposition on a matrix:
Out[]=
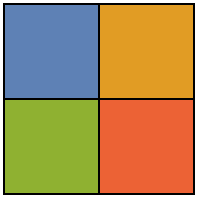
Transpose
⟶
If one is very serious about keeping the convention of linear algebra for vectors (as a row matrix or an column matrix), then one should consider a construct as ={{,}}. However, I will adopt the usual Mathematica’s convention with ={,}.
1×n
n×1
v
v
1
v
2
v
v
1
v
2
If one is very serious about preserving the usual linear-algebra convention, treating vectors explicitly as either a row matrix or an column matrix, then it can be helpful to represent a “row vector” as a nested list. For example, one may define ={{,}} which is a matrix in Mathematica. In that representation, operations like Transpose behave exactly as in linear algebra, converting ={{,}} into the corresponding matrix ={{},{}}. However, in what follows I will adopt Mathematica’s usual convention and represent a vector simply as a one-dimensional list, ={,}, keeping in mind that this suppresses the row/column distinction unless we deliberately reintroduce it.
1×n
n×1
v
v
1
v
2
1×2
v
v
1
v
2
2×1
T
v
v
1
v
2
v
v
1
v
2
Verify that transposition does not change ={,}:
v
v
1
v
2
In[]:=
Withvec=Arrayv.,2,Transpose[vec]==vec
Out[]=
True
Verify that transposition changes ={{,}}:
v
v
1
v
2
In[]:=
Withvec=Arrayv.,2,Transpose[{vec}]===vec
Out[]=
False
Computational Basis and Superposition
Computational Basis and Superposition
Verify that stacking the computational basis vectors as the rows of a matrix yields the identity matrix:
The Bloch Vector Map: Turning a Qubit into Geometry
The Bloch Vector Map: Turning a Qubit into Geometry
Verify that the norm of the Bloch vector is equal to the squared norm of the state vector:
Therefore, the norm of the Bloch vector for a normalized pure state is always 1. This means that, as we consider all possible normalized pure qubit states, their Bloch vectors lie on the unit sphere in three dimensions. This unit sphere is called the Bloch sphere (or the Poincaré sphere in the context of optics).
Visualize the Bloch sphere:
As you can see, the axes are labeled in a particular way. These labels correspond to kets that represent eigenstates of the Pauli matrices. We shall discuss them in more detail later.
There are, of course, different conventions for denoting these kets. For example, in optics it is common to use different labels for the same states, such as those corresponding to horizontal/vertical, diagonal/antidiagonal, or right/left circular photon polarization.
Visualize the Bloch sphere using labels from Optics:
The Bloch Vector: Cartesian and Spherical Coordinates
The Bloch Vector: Cartesian and Spherical Coordinates
As one can see, angles θ and ϕ are exactly the standard spherical coordinates on the unit sphere.
Now the motivation for having θ/2 in the state vector is clear: if we used θ instead of θ/2, the components of the Bloch vector would involve 2θ, and we would obtain an extra factor of 2 in the spherical angles on the Bloch sphere.
Pauli Matrices Appear: Axes, Eigenstates, and Bloch-Sphere Landmarks
Pauli Matrices Appear: Axes, Eigenstates, and Bloch-Sphere Landmarks
Let’s look at the Bloch sphere again.
As mentioned, the axis labels correspond to kets that represent eigenstates of the Pauli matrices.
Show matrix form of Pauli operators (matrices) together with the identity operator:
Calculate the eigenvalues of Pauli-X:
Calculate the eigenstates of Pauli-X:
If we multiply an eigenstate by a nonzero constant, it is still an eigenstate of the same operator with the same eigenvalue.
Let’s plot normalized eigenstates of Pauli-X operator in the Bloch sphere.
Calculate Bloch vectors corresponding to eigenstates of Pauli-X:
Compute Bloch vector for eigenstates of Pauli-Y:
Plot eigenstates of Pauli-Y in the Bloch sphere:
Plot eigenstates of Pauli-Y in the Bloch sphere using optics labels:
The computational basis corresponds to the eigenstates of Pauli-Z and is aligned with the z-axis.
Plot eigenstates of Pauli-Z in the Bloch sphere:
Compute Bloch vectors for eigenstates of Pauli-Z:
The conjugate transpose (also called the Hermitian conjugate in quantum mechanics) of a matrix is obtained by taking the transpose (switching rows and columns) and then taking the complex conjugate of each entry. The order of these two operations does not matter: you can transpose first and then conjugate, or conjugate first and then transpose.
For a 2x2 matrix, visualize diagonal and off-diagonal elements:
Verify that Pauli operators are Hermitian:
For a generic 2×2 Hermitian matrix, verify that eigenvalues are always real:
Let’s also verify these features numerically by generating a random 2×2 Hermitian matrix and checking that its diagonal entries are real, its off-diagonal entries are complex conjugates of each other, and its eigenvalues are real.
Verify that this matrix is Hermitian:
Verify that its diagonal entries are real:
Verify that its off-diagonal entries are complex conjugates of each other:
Verify that its eigenvalues are real:
Additionally, for a Hermitian operator, eigenstates corresponding to different eigenvalues are orthogonal.
Verify that the eigenstates of the numerical Hermitian operator above are orthogonal:
Changing Basis: Unitary Matrices as Basis Machines
Changing Basis: Unitary Matrices as Basis Machines
Verify that it is unitary:
In the Wolfram Language, one can directly check if a matrix is unitary or not, using UnitaryMatrixQ.
Stack new vectors as the rows of a matrix, and verify the result is unitary:
Stack new vectors as the columns of a matrix, and verify the result is unitary:
Coordinates of the Same State in Different Bases
Coordinates of the Same State in Different Bases
Now let’s discuss how to compute the representation of qubit states in a new basis.
Define a normal random state vector:
Compute the normalization factor (which is expected to be 1):
Verify explicitly the orthonormality of new basis elements:
Compute the state vector in the new basis:
Let’s perform a similar calculation in a different basis. This time, consider the normalized eigenstates of the Pauli-X operator.
Verify that these states form an orthonormal set:
Compute the state vector in the Pauli-X basis:
Note that although the coordinate representation of a state vector is different in different bases, the physical state itself is the same. If you reconstruct the state by taking the appropriate linear combination in any given basis, you obtain the same vector in Hilbert space, as expected.
Measurement as Probabilities: Born Rule in the Eigenbasis
Measurement as Probabilities: Born Rule in the Eigenbasis
What is the main motivation for expressing a state in different bases? Besides mathematical advantages that may simplify calculations, an especially important reason comes from quantum measurement. Experimental data are obtained as probabilities for different measurement outcomes, and these probabilities can be read directly from the coefficients in the expansion of the state in a chosen basis.
Expectation Values: Two Equivalent Computations
Expectation Values: Two Equivalent Computations
Before we move on to the next topic, let us summarize the most important points we have learned so far:
◼
A pure state of a single qubit can be represented by a two-component vector {α, β}, where α and β are complex numbers, also called as quantum amplitudes in a given basis.
◼
The above representation is always defined with respect to a chosen basis. Always keep that in mind: the components {α, β} tell you how the state is expanded in that particular basis
◼
There are infinitely many ways to choose a basis, and the choice depends on many factors, often computational convenience. In practice, eigenbases of observables are among the most commonly used bases.
Note that the measurement description we discussed above is usually called as the projective measurement. Measurements can be beyond projective: positive operator-valued measure (POVM). We shall discuss them later.
Why Pure-State Vectors Aren’t Enough: The Stern–Gerlach Experiment
Why Pure-State Vectors Aren’t Enough: The Stern–Gerlach Experiment
Although many things can be computed using only state vectors and pure states, there are situations where this description is not sufficient. For example, in the famous Stern–Gerlach experiment—where a beam of silver atoms is sent through an inhomogeneous magnetic field—the initial state of the atoms (even if we approximate each atom only by its electron spin) is typically an ensemble of states rather than a single pure state.
No Pure State Can Be Unpolarized in Every Basis
No Pure State Can Be Unpolarized in Every Basis
Compute the measurement probabilities when Pauli-Z is measured:
Using this result, let us compute the measurement probabilities in the Pauli-X basis. We will first transform the state into the eigenbasis of Pauli-X and then calculate the corresponding probabilities.
Compute the state in the eigenbasis of Pauli-X:
Impose the condition on θ and calculate probabilities:
So far, we have found pure states that give probability 1/2 for each outcome in measurements of both Pauli-X and Pauli-Z. Now we turn our attention to measurements of Pauli-Y.
If we impose the previous conditions into the measurement probabilities in the Pauli-Y basis, one finds the measurement probabilities can be only 0 or 1, which contradicts the experimental result. Let’s show this explicitly.
Compute the state in the eigenbasis of Pauli-Y:
Find probabilities after imposing conditions for θ and ϕ:
The result shows that the pure state cannot yield 1/2 measurement probabilities in every basis. This motivates a more general description of quantum states using a density matrix. First, we will focus on the density matrix description of pure states and then we will introduce another class of states called the mixed states that can fully describe Stern-Gerlach experimental results.
Density Matrices: What They Are and How to Read Their Entries
Density Matrices: What They Are and How to Read Their Entries
Show the matrix form of a 2x2 density matrix:
Define the computational basis:
Define a 2x2 density matrix:
Basis-Dependence Returns: Density Matrices in Different Bases
Basis-Dependence Returns: Density Matrices in Different Bases
As one can see, much like the state vector, the density-matrix representation also depends on the chosen basis. In a different basis, it takes a different matrix form, even though it describes the same physical state. Let’s remind ourselves of this feature by doing some computations for the state vector first, and then we will extend the same idea to the density matrix.
Consider a symbolic state vector in the computational basis:
Calculate its presentation in the Pauli-Y basis:
Outer Products and Projectors
Outer Products and Projectors
Expectation Values via Trace
Expectation Values via Trace
Hermiticity Condition on Density Matrices
Hermiticity Condition on Density Matrices
Pauli operators are traceless matrices, meaning their trace is zero.
Verify that Pauli operators are traceless:
Positivity, Eigenvalues, and the Meaning of Bloch Vector’s Length
Positivity, Eigenvalues, and the Meaning of Bloch Vector’s Length
The density matrix must be positive semidefinite, which is the mathematical way of saying that all predicted probabilities are nonnegative. This implies that all eigenvalues of the density matrix must be nonnegative. To explore this, first let’s calculate the eigenvalues of the density matrix.
Transform the Bloch vector from Cartesian coordinate to spherical one:
Transforming the Bloch vector from spherical coordinate to Cartesian one:
Purity and von Neumann Entropy: Quantifying Mixedness
Purity and von Neumann Entropy: Quantifying Mixedness
Calculate the density matrix of above example:
Verify that the above state is mixed by calculating its purity:
which is less than one, thus the state is a mixed state.
Let’s generalize the function BlochVector we introduced before so that it also accepts density matrices and returns the corresponding Bloch vector.
Compute the Bloch vector (in Cartesian coordinates) for the mixed state defined above:
Hilbert–Schmidt Operator Basis: Why the Pauli Expansion Always Works
Hilbert–Schmidt Operator Basis: Why the Pauli Expansion Always Works
Calculate the determinant of the Gram matrix:
How Density Matrices Transform Under Basis Change
How Density Matrices Transform Under Basis Change
Find the change-of-basis (unitary) matrix that transforms state coordinates from the Pauli-Y to the Pauli-X basis:
Note that the density matrix is in the Pauli Y basis. Now transform it into Pauli-X basis:
Confirm the result is the same as the state vector transformation in the previous step:
Now that we can represent states geometrically, let’s focus on their movement: what operations move us around the Bloch sphere, and how does the algebra of those operations encode 3D rotations?
Unitaries and SU(2): The Home of Single-Qubit Dynamics
Unitaries and SU(2): The Home of Single-Qubit Dynamics
Define a function that generates random special unitary matrices (elements of SU(2)) sampled from the Haar measure:
Lie Groups and Lie Algebras: Generators, Exponentials, and Conventions
Lie Groups and Lie Algebras: Generators, Exponentials, and Conventions
You may have noticed we used the term “group” when referring to SU(2). What is a group in this context? A group is a set of objects that you can compose (or “multiply”) in a way that behaves nicely: (i) combining two objects keeps you inside the set (closure), (ii) there is an identity element that does nothing, and (iii) every element has an inverse that undoes it. In our setting, the objects are matrices and the “multiplication” is ordinary matrix multiplication. So SU(2) is a matrix group: multiply two SU(2) matrices and you get another SU(2) matrix.
What makes SU(2) especially important in quantum mechanics is that it’s also continuous: its elements vary smoothly with real parameters, and you can move from one element to a nearby one by making an arbitrarily small change. A group equipped with this kind of smooth structure is called a Lie group.
Once we know the group is smooth, it makes sense to study it “from the inside out”: start at the identity (the “do nothing” transformation) and ask what infinitesimal transformations are possible. The collection of these infinitesimal directions is the Lie algebra. The Lie group describes finite transformations, while the Lie algebra describes the infinitesimal generators that, when exponentiated, produce finite transformations.
Verify that Pauli operators are also traceless:
Commutators, Levi–Civita, and the Pauli Product Identity
Commutators, Levi–Civita, and the Pauli Product Identity
Dimensions of 3D Levi-Civita tensor:
Visualize 3D Levi-Civita tensor:
From Algebra to Rotations
From Algebra to Rotations
SU(2) Acts as SO(3) on the Bloch Vector
SU(2) Acts as SO(3) on the Bloch Vector
Show two results are the same:
In short, a single qubit can be pictured as a point on the Bloch sphere, and unitary transformations of qubit state act like rotations of that sphere. SO(3) is the mathematical name for ordinary 3D rotations of that Bloch-sphere “arrow,” the same kind of rotations you’d apply to a rigid object in space.
SU(2) is the mathematical home of the actual qubit operations themselves (again, focusing on the “pure rotation” part and ignoring overall global phase). When you apply an SU(2) operation to the qubit’s state, its visible effect on the Bloch sphere is an SO(3) rotation. The Lie algebra (2) is the “infinitesimal” version of SU(2): it describes the instantaneous, tiny rotation tendencies you can apply at the identity operation. Practically, (2) is where the generators live (the basic rotation directions you can turn on for a short time), and exponentiating those infinitesimal generators produces the finite SU(2) unitaries you use on a qubit.
SU(2) is the mathematical home of the actual qubit operations themselves (again, focusing on the “pure rotation” part and ignoring overall global phase). When you apply an SU(2) operation to the qubit’s state, its visible effect on the Bloch sphere is an SO(3) rotation. The Lie algebra (2) is the “infinitesimal” version of SU(2): it describes the instantaneous, tiny rotation tendencies you can apply at the identity operation. Practically, (2) is where the generators live (the basic rotation directions you can turn on for a short time), and exponentiating those infinitesimal generators produces the finite SU(2) unitaries you use on a qubit.
The Double Cover: Why 2π Looks Like Identity on the Sphere but Not in SU(2)
The Double Cover: Why 2π Looks Like Identity on the Sphere but Not in SU(2)
That said, there is a subtlety worth some discussion. SU(2) contains more information than the Bloch arrow shows: two different SU(2) operations can produce the exact same SO(3) rotation on the Bloch sphere, differing only by an overall sign on the underlying state. That’s why a 360° rotation returns the Bloch arrow to itself but does not fully return the underlying SU(2) description; you need 720° to come back exactly.
Splitting Exponentials and Ignoring the Identity Term (Zassenhaus Insight)
Splitting Exponentials and Ignoring the Identity Term (Zassenhaus Insight)
Euler Angles: Decomposition of a Unitary Transformation
Euler Angles: Decomposition of a Unitary Transformation
For two Bloch vectors, visualize the plane spanned by them and also the perpendicular vector defining it:
Make the above results numeric:
Projectors as Measurements: Yes/No Questions and State Filtering
Projectors as Measurements: Yes/No Questions and State Filtering
General Spin Measurement
General Spin Measurement
Born Rule in Bloch Form
Born Rule in Bloch Form
Beyond Projective Measurements: POVMs
Beyond Projective Measurements: POVMs
POVMs: Post-Measurement States
POVMs: Post-Measurement States
POVMs and Quantum Channels
POVMs and Quantum Channels
Visualize the change in the available space in the Bloch sphere due to unsharp X-measurement:
POVMs: Same Statistics, Different Measurements
POVMs: Same Statistics, Different Measurements
Visualize the change in the available space in the Bloch sphere due to unsharp X-measurement:
When you “add a unitary” to a Kraus operator, you are not changing the measurement’s readout statistics, you are changing what happens to the quantum state after the measurement reports an outcome. Think of it as wiring an extra control box after the detector: first the detector produces an outcome label (like “+” or “−”), and then, depending on which label appeared, the control box applies a rotation to the qubit.
The crucial point is that the POVM effects determine only how often each label appears, not what the device does to the state. So you can keep the same effects (and therefore the same outcome probabilities for every input state) while modifying the back-action by appending an outcome-dependent unitary. In practice, this models real experiments where you do feedback, actively correct errors, or simply have hardware that naturally applies a conditional phase or rotation as part of the readout process.
What changes, then, are the post-measurement states. If you look at the state conditioned on a particular outcome, it will generally be a rotated version of the state you would have gotten without that extra unitary. That means if you repeat the measurement, or if you use the post-measurement state as the input to later gates, the subsequent behavior can be very different—even though the measurement’s raw outcome frequencies are identical. In other words, you can make two devices that “report the same results with the same probabilities,” but one of them leaves the system gently nudged toward an eigenstate, while the other one nudges it and then also kicks it (rotates it) in a way that depends on the outcome.
Time Evolution: Schrodinger Equation
Time Evolution: Schrodinger Equation
Show the value of the reduced Planck constant:
Calculate the Bloch vector corresponding to the above solution:
As expected, the Bloch vector computed via the SU(2) unitary evolution agrees exactly with the result obtained from the corresponding SO(3) rotation.
Time Evolution: Stationary States
Time Evolution: Stationary States
The qubit’s time evolution affects measurement outcomes directly: as the state rotates, the measurement probabilities generally become time-dependent and can vary in a measurable way.
This is why Hamiltonian eigenstates are called stationary states: as time evolves, they acquire only a global phase, which is not observable. Consequently, the physical state remains unchanged in time, hence “stationary.”
Time Evolution: the Liouville–von Neumann Equation
Time Evolution: the Liouville–von Neumann Equation
Time Evolution: Pulses
Time Evolution: Pulses
Visualize Gaussian and square pulses:
Drunken Sailor: Open Quantum Systems
Drunken Sailor: Open Quantum Systems
From the very beginning, when we introduced time evolution, we quietly assumed an isolated quantum system: no uncontrolled interactions with anything else. In that ideal setting, the dynamics are unitary and governed solely by the system’s Hamiltonian. In reality, however, almost every quantum system is open: it interacts, often uncontrollably, with its surroundings (the “environment”). Sometimes these environmental couplings are weak or occur on energy/time scales that barely affect the dynamics we care about, so the isolated-system approximation still works well. In many other situations, though, the environment does significantly disturb the system, and we can no longer describe the evolution with a simple unitary propagator. Instead, we must modify our dynamical equations to incorporate these random, uncontrolled influences, this is the central idea behind the theory of open quantum systems.
How do we model random features in the dynamics? Let’s consider a simple example.
Imagine a sailor leaving a pub at night and walking along a long, straight dock. Every second, the sailor takes exactly one step. Because they are drunk, each step is completely random: with probability 1/2 they move one step to the left, and with probability 1/2 they move one step to the right.
To describe this more precisely, imagine the dock divided into equally spaced markers labeled by integers: …, -2, -1, 0, 1, 2, …. The sailor starts at marker 0. After 1 second, they are either at marker +1 (one step to the right) or -1 (one step to the left). After 2 seconds, depending on the sequence of coin-flip-like choices, they might be at +2, 0, or -2. After many steps, their position is some random integer that tells us how far they have wandered from the starting point and in which direction.
This process is called a random walk. In this simple model, time is discrete (1 step, 2 steps, 3 steps, …) and space is also discrete (the sailor can only stand on integer-labeled positions along the dock).
Define a random walk with probability of 1/2 for moving forward or backward:
Simulate random paths:
As you can see, each time the sailor walks, the sequence of random steps is different, so the trajectory is different and the final position of the drunk sailor also changes from one realization to the next. On average, the sailor tends to stay around the starting point. But sometimes, purely by chance, they drift far to one side. The path is jagged and unpredictable step by step, but statistically we can analyze it.
Visualize the histogram of the final position of drunken walks
From Sailor to Brownian Particle
From Sailor to Brownian Particle
Now imagine modifying the drunken sailor’s walk in a particular way. You make each step much smaller – tiny nudges instead of full strides – and you make the steps happen much more frequently, many times per second. In this limit, the sailor no longer appears to jump from marker to marker along the dock. Instead, their position wiggles and wobbles almost continuously, with no obvious pauses between steps. The motion is still random, but it now looks like a continuous, jittery path rather than a sequence of discrete hops. This continuous, randomly fluctuating motion is what we call Brownian motion. In other words, one-dimensional Brownian motion can be thought of as the continuous-time limit of the drunken sailor’s random walk along a line.
A classic physical picture of Brownian motion comes from a tiny grain of pollen or dust floating on the surface of water. To the naked eye, the water seems perfectly still. But under a microscope, the grain does something strange: it jitters, jiggles, and wanders in an irregular way. It does not glide smoothly in a straight line. Instead, it moves in a constantly changing, erratic pattern. The underlying reason is that the water is not truly at rest. It is filled with water molecules moving rapidly due to thermal motion, and these molecules continuously collide with the larger pollen grain from all directions.
Because the grain is much larger than the water molecules, it feels this microscopic bombardment as a sequence of tiny, random kicks. At any instant, the kicks are not perfectly balanced: sometimes there is a bit more push from the left than from the right, or a slightly stronger push from below than from above. As a result, the grain is constantly nudged around in a random fashion. This persistent, irregular motion driven by countless unseen collisions is what we call Brownian motion.
The key ideas are: on short time scales and at the microscopic level, the motion looks highly irregular and is impossible to predict step by step. However, when you look over longer times and across many realizations, the average behavior becomes very regular and can be described statistically. Importantly, we never try to track every individual collision between water molecules and the grain. Instead, we model their combined effect as random kicks that produce the observed Brownian motion.
In reality, the grain moves in two or three dimensions: on the surface of the water or within the fluid. However, to understand the basic idea, it is often enough to focus on just one coordinate, for example its horizontal position along some line. The full trajectory in space is a wiggly path, but if you look only at its projection onto that line, you see a one-dimensional record of how it wanders left and right over time. That single coordinate already captures the essential randomness and statistical behavior. For this reason, we usually start by studying one-dimensional Brownian motion: it is simply a description of how far left or right a particle has wandered along a line as time goes on.
Generate an Ito process for a one-dimensional Brownian motion with the diffusion constant :
Note in above we used another common notation for mean and variance.
Visualize the histogram of the final position of one-dimensional Brownian motion:
As expected, the numerical simulations show that the ensemble of final positions follows a normal distribution, with mean and standard deviation matching the theoretical predictions.
Noisy Phase of a Laser: Brownian Motion!
Noisy Phase of a Laser: Brownian Motion!
Visualize an ideal laser’s electric field:
In the real world, a laser is never perfectly clean. It is driven by noisy electronics, mounted on a vibrating table, and coupled to atoms and electromagnetic fields in the cavity that are constantly fluctuating. These imperfections show up primarily as small, random fluctuations in the laser’s phase. The amplitude can remain relatively stable, but the phase does not stay fixed; it drifts and jitters in time. Instead of a perfectly steady phase, you should picture something like the hand of a clock that advances almost uniformly, but is continually given tiny random nudges forward and backward. This is the essence of the noisy phase picture.
As you can see, when the diffusion constant κ is small, the noisy phase stays very close to the ideal deterministic laser, so the Brownian-motion correction to the dynamics is tiny. As κ increases, the phase diffuses more strongly and the laser field deviates more noticeably from the ideal case.
Now imagine generating a large ensemble of noisy laser traces, each one a different realization of the fluctuating phase. By averaging the electric field over all these realizations at each instant of time, we obtain the noise-averaged behavior of the laser field: the underlying coherent oscillation with the damping effect of phase noise washed into a smooth, averaged signal.
Compute the mean value of electric field (i.e., noise-averaged), given its Ito process:
As you can see, the noisy phase effectively shows up as an exponential damping of the electric field when you look at it over time. To make this more concrete, we can confirm it numerically: generate many different realizations of the laser’s electric field with the same noise statistics, and then compute the average field at each time. This ensemble average will reveal how the coherent oscillation decays due to phase diffusion.
So let’s rephrase what our simple model is describing. Imagine that at time zero you line up a huge number of microscopic oscillators (e.g., atoms) all with exactly the same phase. In that instant they behave like one big classical arrow/dipole: all the little arrows on the complex plane point the same way and add up to a large net arrow. The electromagnetic field radiated by this ensemble is essentially proportional to that net arrow, i.e. to the ensemble-averaged electric field. So, at the beginning, the “signal” you care about really is the mean field of this collection of oscillators.
As phase diffusion progresses, the individual microscopic oscillators wander in phase and partially cancel, so the mean field decays in time. In our model, that decay is an exponentially damped oscillation. Now given this mechanism, how much power does this thing emit at each frequency? This is what we call as the spectral density. When you ask for the spectral density, you’re really asking, “What is the frequency content of this coherent transient emitted by the decaying dipole?” The appropriate object to Fourier transform is the time-dependent field produced by that dipole, i.e. the mean electric field itself. Because its envelope decays exponentially, its spectrum is Lorentzian, with the linewidth set by the same rate that controls the loss of coherence.
Calculate the spectral density by computing the Fourier transform of the mean electric field:
Visualize the spectral density:
Visualize the two-time correlation functions:
White Noise: Stratonovich Viewpoint
White Noise: Stratonovich Viewpoint
Verify that the two-time correlation function of a white noise is Dirac delta:
Confirm that the spectral density of a white noise (i.e., Fourier transform of its two-time correlation) is constant/flat:
Both of the expressions we derived above are written in terms of the Cartesian components of the Bloch vector. However, our goal is to describe the dynamics in spherical coordinates. To do that, we need two additional steps: first, use the Jacobian of the coordinate transformation to rewrite the results in spherical coordinates; second, wherever Cartesian components still appear, replace them with their explicit expressions in terms of the spherical variables.
Generate 1,000 realization of SDE for the density matrix:
Visualize Cartesian component of Bloch vector for two realizations of random trajectory:
Visualize Bloch vector for two realizations of random trajectory on the Bloch sphere:
In analogy with our earlier random-process simulations, a natural question is: what does the density matrix do on average? In other words, if we average over the stochastic fluctuations and keep only the deterministic part, what effective dynamical equation governs the noise-averaged density matrix? Let’s now work this out and see what form that equation takes.
From Noise-Averaging to the Lindbald Equation
From Noise-Averaging to the Lindbald Equation
Let us first examine the many individual realizations we have generated and study their average behavior. This average defines an effective trajectory on the Bloch sphere that represents the ensemble of qubits governed by the random Hamiltonian we are considering. In other words, instead of following a single noisy Bloch vector, we now look at the mean Bloch vector, which captures how the ensemble as a whole evolves under the stochastic dynamics.
Show the noise-averaged trajectory of the Cartesian components of the Bloch vector (the time evolution of the ensemble-averaged qubit state as it moves on the Bloch sphere:
Visualize the noise-averaged trajectory in the Bloch sphere:
Transform the Stratonovich-form stochastic dynamical equation into its equivalent Itô form, so that the noise terms are written with standard Wiener increments and can be averaged using the usual Itô rules:
Plot the time-evolution of the Bloch vector in Cartesian coordinate:
As you can see, this agrees with the result we found earlier by numerically averaging over 1,000 noise realizations, up to the small discrepancies expected from numerical error and the finite number of samples.
For 1,000 noise realizations, evaluate the norm of the difference between the numerically noise-averaged Bloch vector and the Bloch vector predicted by the Lindblad equation, over time:
Collapse as Dynamical Equation and not a Postulate
Collapse as Dynamical Equation and not a Postulate
Compute the non-random terms in the SDE:
Compute the random terms in the SDE:
Dimensions of Jacobian:
Dimensions of Hessian:
Use the result to obtain the Itô-form SDE for the spherical coordinates:
Check if the new process is a valid random process:
Generate 100 different realization (trajectories) of the random process:
Given 100 different realization, compute Bloch trajectories:
For all simulated trajectories (ensemble), extract the z-component of the Bloch vector at a chosen time and plot its histogram:
Visualize histograms:
Where This Leaves Us (and What Comes Next)
Where This Leaves Us (and What Comes Next)
You now have a complete, computation-first toolkit for understanding a single qubit from multiple, consistent viewpoints: state vectors and bases, the Bloch-sphere and Bloch-ball geometry, how measurement probabilities and expectation values are extracted, why density matrices are necessary for ensembles and mixedness, how unitary dynamics are built from the Pauli algebra and organized by the SU(2) to SO(3) relationship (including the subtle double-cover point), and how those unitaries can be implemented dynamically based on Schrodinger equation. With these ideas unified, the notebook’s core message becomes practical: prepare a state, change representation when it helps, evolve it with a unitary map, and read predictions directly from the appropriate measurement operators, always able to cross-check algebra with geometry. From here, the most natural continuations are to move beyond ideal projective measurements into more general measurement models, and to treat realistic dynamics such as noise and decoherence, which turn isolated-system rotations into open-system evolution and make the Bloch-ball picture even more valuable.
CITE THIS NOTEBOOK
CITE THIS NOTEBOOK
Qubits explained: Bloch sphere, SU(2) rotations, time evolution, and measurements
by Mohammad Bahrami
Wolfram Community, STAFF PICKS, December 3, 2025
https://community.wolfram.com/groups/-/m/t/3585466
by Mohammad Bahrami
Wolfram Community, STAFF PICKS, December 3, 2025
https://community.wolfram.com/groups/-/m/t/3585466