Introduction
Introduction
This notebook (article) discusses several topics:
◼
Making nice plots of chess positions
◼
◼
Staging and interactively using a Large Language Model (LLM) persona for playing chess
◼
Using LLM-vision over chess position images
◼
◼
A conjecture is formed using a few experimental results
◼
The article showcases utilization of the Wolfram Language (WL) chatbooks, LLM functions, and LLM prompts.
In other words, the article has:
◼
Two WL know-how topics: plotting chess positions and LLM persona making and interaction
◼
A general know-why topic: reasons for LLM-deficiencies while using FEN
The last section “Leftover comments” briefly discusses a comparison with Raku over the content of the notebook.
Remark: Playing chess (really) well with LLMs is not the focus of this article.
TL;DR
TL;DR
◼
◼
Marveling at the restyled, colorized chess position plots is encouraged.
◼
The main message of the notebook is in the section "Possible explanations".
◼
Asking LLMs to play chess via FEN is counter-productive.
◼
FEN "compresses" field data and LLMs are not good at predicting those kind of sequential compressions.
On chess playing
On chess playing
There are plenty of (research) articles, posts, software packages, or coding projects about LLMs-and-chess . (For example, see [DM1, NC1, NCp1, MLp1].)
At least half a dozen of those articles and posts proclaim much better chess playing results than the examples given below.
Those articles, posts, or projects, though, use:
◼
Well known chess games
◼
Notations other than FEN
◼
Textual/ASCII chess position representation
◼
Connections to 3rd party programs
In this article the focus is not on playing chess well by LLMs. Article's main message is that WL can be used to facilitate chess playing, exploration, or puzzle solving. (With LLMs or otherwise.)
LLM persona -- ChessMaster
LLM persona -- ChessMaster
Here is the prompt of an LLM persona for playing chess:
You are a ChessMaster engaged in a text-based chess game. You play the opponent, usually with the black chess pieces and pawns.
The game should be easy to follow and adhere to standard chess rules.
Here is how you behave:
- Use Forsyth-Edwards Notation (FEN) strings to communicate the state of the gameplay.
- Ensure you play by standard chess rules.
- Ensure the game interprets and executes these moves correctly.
- Allow the player to input using:
1. Algebraic Notation (AN) input, for example, "e2 to e4" to move a pawn
2. Descriptive input, like, "bishop from a3 to f8"
- When the user gives you AN string you respond with three strings:
1. FEN position after user's AN input is played
2. Your move given as AN string
3. FEN position after your AN move is played
- If asked provide clear feedback to the player after each move, including the move itself.
- For example, "You moved: e2 to e4" and "Opponent moved: e7 to e5".
- If you take a piece of the user then make sure to say that in your responses.
- If asked provide player guidance
- Include in-game guidance resources or instructions that explain chess rules, move input, and special conditions like check and checkmate.
- Proclaim when the user gives you AN move that is wrong, noncompliant with the standard chess rules.
- When the user asks you to start a game without specifying a FEN string:
- You give the standard initial position as start.
- You play the black opponent, the user plays the white, except if the user says that he plays the black side.

This is a comprehensive and detailed guide for an LLM persona designed to play chess. The ChessMaster persona is programmed to understand and communicate chess moves using Forsyth-Edwards Notation (FEN), and can also interpret user inputs in Algebraic Notation (AN) or descriptive language.
The ChessMaster persona follows standard chess rules and provides feedback to the player after each move. It can also provide guidance on chess rules, move inputs, and special conditions like check and checkmate.
This persona is mainly designed to play as the black opponent, but it can also play as the white opponent if specified by the user.
The ChessMaster persona is a great example of how a Large Language Model (LLM) can be used to create an interactive and engaging chess-playing experience.
A few observations on the prompt above:
◼
The prompt is carefully crafted.
◼
Other research efforts often use much shorter prompts like "You are chess master."
◼
FEN is explicitly postulated as the way to communicate the "game field."
◼
Both AN and plain English are "allowed" as user inputs.
Remark: Below the LLM persona is referred to as "ChessMaster" or "CM".
Chess position plotting setup
Chess position plotting setup
This section shows the setup for plotting chess positions while using a WL chatbook.
Load paclets:
In[]:=
(*PacletInstall["Wolfram/Chess"]*)Needs["Wolfram`Chess`"]
Styling options, (default and "greens"):
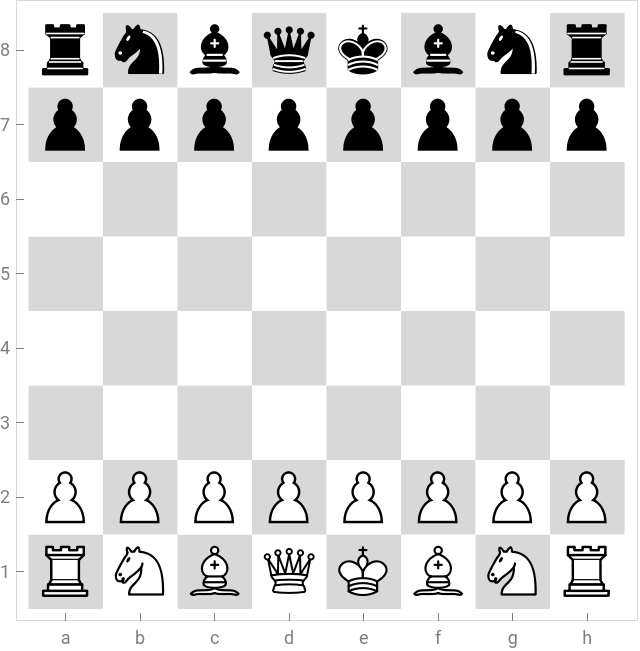
Examples of an initial chess position plot (without using a FEN string) and a blank chessboard:
In[]:=
Row[{Chessboard[]["Graphics",ImageSize->350],Spacer[10],Chessboard[None]["Graphics",ImageSize->350]}]
Out[]=

Make the base chessboards greener (or browner):
In[]:=
baseBoard=;baseBoardGreen=baseBoard/.{GrayLevel[1]->,GrayLevel[0.85]->};baseBoardBrown=baseBoard/.{GrayLevel[1]->,GrayLevel[0.85]->};

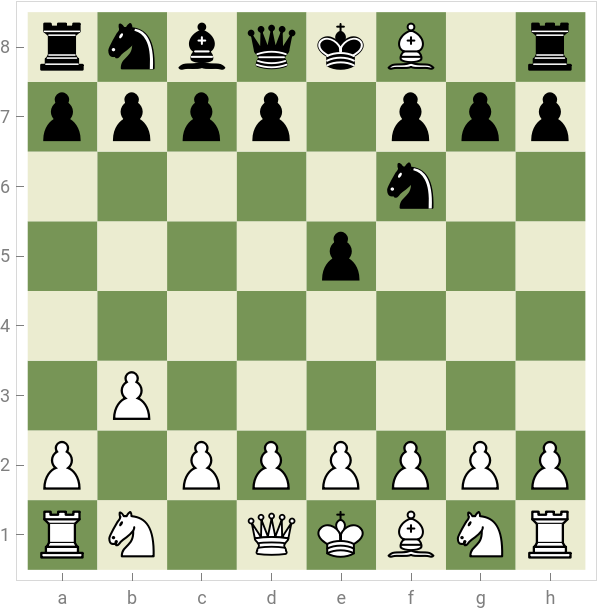
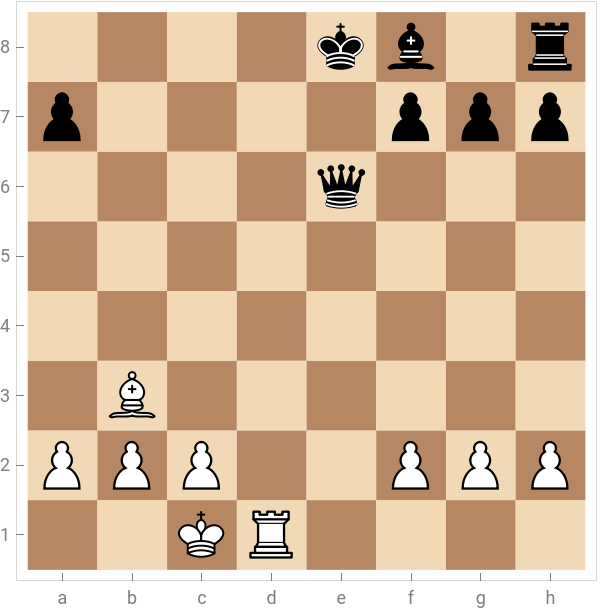
Using a different plotting style with non-trivial FEN strings:
In[]:=
Row[{Chessboard["rnbqkB1r/pppp1ppp/5n2/4p3/8/1P6/P1PPPPPP/RN1QKBNR b KQkq - 0 3"]["Graphics",ImageSize->300]/.{baseBoard->baseBoardGreen},Spacer[10],Chessboard["4kb1r/p4ppp/4q3/8/8/1B6/PPP2PPP/2KR4 w -- 2 21"]["Graphics",ImageSize->300]/.{baseBoard->baseBoardBrown}}]
Out[]=
Let us define a function that prints a row of chessboards:
In[]:=
Clear[ToChessboardRow];Options[ToChessboardRow]=Join[{"WhiteSquareColor"->Automatic,"BlackSquareColor"->Automatic},Options[Graphics]];ToChessboardRow[fen_String,opts:OptionsPattern[]]:=ToChessboardRow[{fen},opts];ToChessboardRow[fens:{_String..},opts:OptionsPattern[]]:=Block[{wColor,bColor,rules,newBoard},wColor=OptionValue[ToChessboardRow,"WhiteSquareColor"];bColor=OptionValue[ToChessboardRow,"BlackSquareColor"];rules={};If[ColorQ[wColor]||ColorQ[bColor],wColor=If[TrueQ[wColor===Automatic],GrayLevel[1],wColor];bColor=If[TrueQ[bColor===Automatic],GrayLevel[0.85],bColor];newBoard=baseBoard/.{GrayLevel[1]->wColor,GrayLevel[0.85]->bColor};rules={baseBoard->newBoard}];Row[Riffle[Map[Chessboard[#1]["Graphics",FilterRules[{opts},Options[Graphics]],ImageSize->300]/.rules&,fens],Spacer[10]]]];
FEN strings processing
FEN strings processing
In[]:=
(*FunctiontoconvertassociationtoFENstring*)Clear[ToFENString];ToFENString[associations_List]:=Module[{board,rows,fenString},(*Initializeanempty8x8board*)board=ConstantArray["1",{8,8}];(*Mapeachassociationtotheboard*)Do[With[{x=associations[[i]]["x"],y=associations[[i]]["y"],z=associations[[i]]["z"]},board[[9-ToExpression[y],ToCharacterCode[x]-ToCharacterCode["a"]+1]]=z],{i,Length[associations]}];(*ConverteachrowtoFENnotation*)rows=StringJoin@@@(StringReplace[#,{x:RegularExpression["1+"]:>ToString[StringLength[x]]}]&/@(StringJoin/@board));(*Joinrowswith'/'toformtheFENstring*)fenString=StringJoin[Riffle[rows,"/"]];(*AppendadditionalinformationforFEN*)fenString<>" w - - 0 1"];
Example of conversion to FEN:
A function to check whether the argument is a FEN string or not:
Wrong FEN verification:
Chess notation sub-strings extraction
Chess notation sub-strings extraction
In this section are given several methods for extracting FEN strings from (free) text strings. (I.e. chess LLM outputs.)
Here is a typical output the LLM ChessMaster persona:
Here is an example using the function FENCorrectQ for FEN strings extraction based on inline code fences:
Remark: The function Chessboard “Wolfram/Chess” accepts only “full” FEN strings. I.e. strings like “rnbqkbnr/pppp1ppp/8/4p3/8/1P6/P1PPPPPP/RNBQKBNR” are not accepted.
Example play
Example play
Starting a game:
Let us start a new game.
Plotting the FEN strings from the LLM output:
User first move:
b2 to b3
Plotting the FEN strings from the LLM output:
Another user move:
Bishop from c1 to a3
User move and ChessMaster move:
The chess positions clearly show the wrong LLM move (or FEN string). Trying to fix it:
No, your move is wrong -- you turned my black-squares bishop into a white-squares one.
Well, the LLM fixed the moves:
bishop from a3 to f8
Well we get wrong moves again:
Alternative development
Alternative development
Several other games were played, and, although they developed differently in all of them ChessMaster gave wrong FEN strings within the first 6 moves.
Chess position recognition
Chess position recognition
It is interesting to review the abilities of the vision (or "omni") LLM models to recognize chess positions and produce the (correct) corresponding notation strings.
Remark: (Some of) the LLM-vision models explicitly state that they are not good at recognizing chess positions. (For example, see OpenAI's "Vision/Limitations" .)
Here image's corresponding Base64 string is obtained and rendered:
Remark: The Raku chatbook visualizations via JavaScript and URLs are faster that using Base64 strings.
Here is an LLM vision application (using image's URL):
We can see from the output above that the positions of both the white and black pieces are correctly recognized by the omni-LLM "gpt-4o" .
Again, we can see from the output above that the image was correctly recognized by ChessboardRecongnize. Here is the corresponding FEN string:
Here ask an LLM to convert the textual description into WL code:
Convert to a list of associations:
Here we compare the original image with the image corresponding to its LLM derived description (converted to a WL list of associations):
By comparing the images it can be seen that a correct LLM-vision recognition JSON spec was obtained.
The FEN string of the image is B3R3/8/8/8/4n1p1/5kP1/5P2/R3K1Q1 and it can be obtained from the Chessboard object produced by ChessboardRecognize:
Remark: Below chessPos is considered to be verified equivalent to chessSpec.
LLM configurations and functions for repeated use
LLM configurations and functions for repeated use
Here are defined LLM-configurations and functions that are used below (more than once):
Using FEN strings is counter-productive
Using FEN strings is counter-productive
In this subsection we demonstrate that LLMs have hard time converting correctly from- or to FEN strings.
Get FEN string corresponding to the LLM-obtained image description:
Instead of a "plain English" description, request a FEN string to be returned for the given image:
Using one of latest Gemini's vision/omni models (with Gemini's vision models image Base64 strings have to be used instead of image URLs):
Verify the correctness of the FEN string obtained from Gemini:
Here is a comparison of the original image (top left) and the chess position plot based on LLM recognitions above:
Here are a few observations:
◼
The FEN-titled images shows several types mistakes. We have observed:
◼
Chess pieces misplacement or omissions
◼
White have no king or three rooks
◼
Pieces are in the wrong locations
◼
Wrong spaces between the chess pieces
◼
Rows that too long or too short
◼
We can say that the tried LLMs do not faithfully convert into FEN specs that are:
◼
Plain text chess position descriptions
◼
Chess position images
Conjectures
Conjectures
We can conjecture that:
1
.Due to FEN's aggregational nature LLMs have hard time deriving correct FEN representations.
2
.FEN is not sufficiently well represented in the LLMs training data.
◼
I.e. not enough chess games in the training data are using FEN.
We decided that the second conjecture is hard to investigate and confirm. Hence, below we focus on the first conjecture.
Possible explanations
Possible explanations
In this section we ask one of ChatGPT's reasoning models -- "o1-preview" -- to prove or disprove the conjecture formulated above. Here is the prompt:
Reason, prove, dis-prove, or explain the following conjecture:
> The chess Forsyth-Edwards Notation (FEN) has “aggregational nature”, that is why LLMs have hard time
> deriving correct FEN representations from textual descriptions or from images.
Do not talk in generic terms. Be as concrete as possible.
Be moderately concise.
> The chess Forsyth-Edwards Notation (FEN) has “aggregational nature”, that is why LLMs have hard time
> deriving correct FEN representations from textual descriptions or from images.
Do not talk in generic terms. Be as concrete as possible.
Be moderately concise.
Remark: Currently OpenAI’s reasoning models, “o1-preview” and “o1-mini” have an API interface that is different from the rest of the LLMs provided by OpenAI.
◼
It is not trivial to stage the use of those models in WL, hence I used a Raku chatbook; see "Jupyter::Chatbook", [AAp2].
◼
Alternatively, just a direct copy-&-paste from chatgpt.com can be used with conversion to WL notebook cells code using the Wolfram Repository Function (WFR) "ImportMarkdownString".
Two of the LLM responses are given below.
Shorter explanation
Shorter explanation
Yes, the aggregational nature of the Forsyth-Edwards Notation (FEN) does contribute to the difficulty Large Language Models (LLMs) have in deriving correct FEN representations from textual descriptions or images.
In FEN, empty squares within a rank are aggregated and represented by a single digit (1-8), indicating consecutive empty squares. For example, if there are three empty squares between pieces on a rank, they are represented by the digit '3'. This requires precise counting and aggregation of empty squares, which poses challenges for LLMs.
Consider a textual description: "On the 5th rank, there is a rook on the a-file and a knight on the h-file." To convert this into FEN for that rank, the model must:
1
.Place the rook on 'a5'.
2
.Count the empty squares between 'a5' and 'h5', which totals six.
3
.Place the knight on 'h5'.
4
.Represent this rank in FEN as 'R6N'.
This aggregation demands that the model accurately count the number of empty squares and maintain their sequence, a task that involves exact numerical computation and positional tracking.
LLMs, however, generate text based on learned patterns and are not inherently equipped for precise counting or maintaining exact positional information over sequences. They may miscount the number of empty squares or misplace pieces when trying to aggregate, leading to incorrect FEN output.
For example, an LLM might incorrectly generate 'R5N' instead of 'R6N', miscounting the empty squares and thus producing an incorrect representation of the board.
Furthermore, when deriving FEN from images, the model must first interpret the visual information into positional data and then perform the aggregation. Each step compounds the difficulty, especially since LLMs are primarily language-based and not designed for image recognition or detailed numerical tasks.
In contrast, if the notation were explicit—listing each square without aggregation (e.g., representing empty squares with '1's)—the LLM's task would be simplified. It would not need to perform counting or aggregation, reducing the chances of error. For instance, the rank could be written as 'R111111N', directly mapping each square without the need to count and compress empty squares.
Therefore, the aggregational nature of FEN introduces a layer of complexity that requires precise counting and positional reasoning, areas where LLMs currently have limitations. This contributes significantly to their difficulty in accurately deriving FEN representations from textual descriptions or images.
<hr style="width: 60%;">
Longer explanation
Longer explanation
The conjecture states that the Forsyth-Edwards Notation (FEN) has an "aggregational nature," and this characteristic is the reason why Large Language Models (LLMs) have difficulty deriving correct FEN representations from textual descriptions or images. Let's explore this statement in detail to determine its validity.
Understanding FEN and Its Aggregational Nature
FEN is a standard notation for describing a particular position of a chess game. It provides all the necessary information to reconstruct a game position, including:
1
.Piece Placement : The positions of all the pieces on the board.
2
.Active Color : Which player's turn it is (white or black).
3
.Castling Availability : Whether each side can castle kingside or queenside.
4
.En Passant Target Square : If an en passant capture is possible.
5
.Halfmove Clock : The number of halfmoves since the last capture or pawn move (for the fifty-move rule).
6
.Fullmove Number : The number of the full move.
The piece placement portion of FEN uses a specific syntax:
◼
The board is divided into ranks from 8 (top) to 1 (bottom), and each rank is listed from the 'a' file (left) to the 'h' file (right).
◼
Pieces are represented by letters ('K' for king, 'Q' for queen, etc.), uppercase for White and lowercase for Black.
◼
Empty squares are represented by digits from '1' to '8', indicating consecutive empty squares.
◼
Ranks are separated by slashes ('/').
Example :
The starting position in FEN is:
rnbqkbnr/pppppppp/8/8/8/8/PPPPPPPP/RNBQKBNR w KQkq - 0 1
Aggregational Nature Explained
The term "aggregational nature" refers to how FEN aggregates consecutive empty squares into a single digit and compresses the board's information. Instead of listing each square individually, FEN combines adjacent empty squares and uses counts to represent them. This requires:
◼
Counting : Determining the number of consecutive empty squares.
◼
Grouping : Aggregating these counts within each rank.
◼
Sequence Management : Resetting counts when a piece is encountered.
This aggregation reduces redundancy and creates a compact representation but adds complexity to the generation process because it involves precise counting and structuring.
Challenges for LLMs in Generating FEN
LLMs like GPT-4 are designed to predict and generate text based on patterns learned from large datasets. While they excel at understanding natural language and generating coherent narratives, they face challenges with tasks that require:
7
.Precise Counting and Arithmetic : LLMs are not inherently numerically accurate. They can struggle with exact counts, especially over larger sequences.
8
.Strict Formatting Rules : Adhering to rigid syntactic structures without deviation is difficult. Minor errors can occur, disrupting the validity of the entire notation.
9
.Complex Aggregation : Aggregating data accurately across multiple dimensions (e.g., empty squares across ranks) is non-trivial for LLMs.
Deriving FEN from Textual Descriptions
When attempting to convert a textual description of a chess position into FEN, an LLM must:
◼
Parse the Description : Understand the positions of all pieces and empty squares.
◼
Count Empty Squares : Accurately count and aggregate empty squares in each rank.
◼
Apply Syntax Rules : Format the notation correctly, including slashes, piece symbols, and counts.
◼
Include Additional Information : Correctly identify active color, castling rights, en passant targets, and move counts.
Each of these steps requires precision and adherence to specific rules, which are areas where LLMs may falter.
Deriving FEN from Images
Deriving FEN from images adds another layer of complexity:
◼
Visual Recognition : The LLM must first accurately identify each piece and its location from the image.
◼
Spatial Mapping : Map visual data to board coordinates.
◼
Aggregation : As with textual descriptions, aggregate empty squares appropriately.
Image recognition isn't within the native capabilities of text-based LLMs without the integration of specialized computer vision systems.
Is the Aggregational Nature the Main Cause?
While the aggregational aspect of FEN contributes to the difficulty, it's not the sole reason LLMs struggle:
◼
Counting Limitations : LLMs generally have difficulty with tasks requiring exact counts. The need to count empty squares exacerbates this issue.
◼
Symbolic Representation : FEN uses specific symbols and cases (uppercase for White, lowercase for Black), requiring attention to detail.
◼
Context Length : Keeping track of all pieces and empty squares across 64 squares stretches the LLM's ability to maintain context without error.
◼
Error Propagation : A small mistake in one part of the FEN string can invalidate the entire notation.
Conclusion
The conjecture holds merit. The "aggregational nature" of FEN indeed contributes to the challenges LLMs face when deriving FEN representations from textual descriptions or images. The aggregation requires precise counting and grouping, tasks that are inherently difficult for LLMs due to their architecture and training focus.
Therefore, while LLMs are powerful tools for natural language understanding and generation, their current limitations in precise counting, strict formatting adherence, and aggregation make tasks like generating accurate FEN strings particularly challenging.
Potential Solutions
To mitigate these challenges, specialized approaches could be employed:
◼
Augmented Models : Combining LLMs with tools or modules designed for counting and formatting could improve accuracy.
◼
Training Data : Providing more examples of FEN generation during training might help the LLM learn patterns specific to FEN.
◼
Pre-Processing Steps : Breaking down the task into smaller, manageable steps (e.g., handling one rank at a time) could reduce complexity.
Final Thoughts
Understanding the limitations of LLMs in tasks requiring strict precision and aggregation is crucial. While they are adept at many language tasks, recognizing and addressing their weaknesses allows for better application and the development of complementary tools to overcome these challenges.
Leftover comments
Leftover comments
Here is a list of “leftover” comments:
◼
Some of my friends and coworkers have mentioned more than a few times that I am suspiciously weak at playing chess.
◼
◼
And have done so a few times.
◼
The chess plotting functionalities of “Wolfram/Chess” accept only full FEN strings
◼
I.e. strings like “rnbqkbnr/pppp1ppp/8/4p3/8/1P6/P1PPPPPP/RNBQKBNR” are not accepted.
◼
Obviously, a feature, but I consider it a bug.
◼
Facilitating and experimenting with different styles for plotting of the chess positions is/was both interesting and time-consuming.
◼
It would be nice if “Wolfram/Chess” have color tuning options. (Not that important.)
◼
Most of the content of this notebook (article) was written for a Raku-based blog post with the same name; see [AA1].
◼
I had to write in WL the FEN string verification and conversion functions.
◼
◼
It is interesting to compare Raku and WL in the content of this article.
◼
In general, WL has a decisive advantage when it comes to graphics.
◼
And my knowledge how to manipulate them.
◼
Nevertheless, my Raku package, “JavaScript::D3”, [AAp1], used for plotting chessboards is very competitive.
◼
In some ways even better because almost all elements of the chessboard plotting can be tuned.
◼
The Raku and WL workflows using LLMs are almost identical because I have mirrored WL’s LLM-functions and LLM-prompts in Raku. See:
◼
◼
◼
Having an universal importing function like Import is very, very nice!
◼
And not trivial to implement and have.
◼
I miss it in the non-WL systems I use.
◼
I have implemented a Raku package, [AAp3], that has similar mission. (Currently, with much smaller scope.)
◼
◼
That Jupyter notebook was converted into a WL notebook with the Raku package "Markdown::Grammar", [AAp7].
References
References
Articles, blog posts
Articles, blog posts
[AA1] Anton Antonov, "Don't use Forsyth-Edwards notation to play chess with LLMs", (2024), Raku Advent Calendar blog.
Packages, repositories
Packages, repositories
Videos
Videos
[AAv1] Anton Antonov, Robust LLM pipelines (Mathematica, Python, Raku) , (2024), YouTube/@AAA4prediction .
CITE THIS NOTEBOOK
CITE THIS NOTEBOOK
Don't use Forsyth-Edwards notation (FEN) to play chess with LLMs: limitations and alternatives
by Anton Antonov
Wolfram Community, STAFF PICKS, December 4, 2024
https://community.wolfram.com/groups/-/m/t/3332840
by Anton Antonov
Wolfram Community, STAFF PICKS, December 4, 2024
https://community.wolfram.com/groups/-/m/t/3332840