Hi!
I cannot understand the meaning of the NetTrain “Patience” subparameter.
Let us initialize a simple neural net in (WM 14.1)
In[]:=
testNet=NetChain[{LinearLayer["Input"->3,"Output"->3],LogisticSigmoid,LinearLayer["Output"->1]}];testNet=NetInitialize[testNet,Method"Identity"];
and define a train and validation books as follows:
In[]:=
SeedRandom[0];testBook=(#{(Plus@@#)}&)/@Table[RandomReal[NormalDistribution[],3]/3,{i,100}];testTBook=testBook[[;;70]];testVBook=testBook[[71;;]];
We will train it until the loss function on the validation set increases and will use Patience. If to believe the WM documentation, Patiencen ”...specifies that training should be stopped if an improvement in measurement is not seen for n rounds in a row”. Let us check it.
We define the training procedure as follows:
We define the training procedure as follows:
In[]:=
myTrainNet[n_]:=NetTrain[testNet,testTBook,All,TargetDevice->"GPU",ValidationSet->testVBook,MaxTrainingRounds->Infinity,TrainingStoppingCriterion-><|"Criterion"->"Loss","Patience"->n|>]
Let us start with Patience0:
In[]:=
trained0=myTrainNet[0]
Out[]=
NetTrainResultsObject

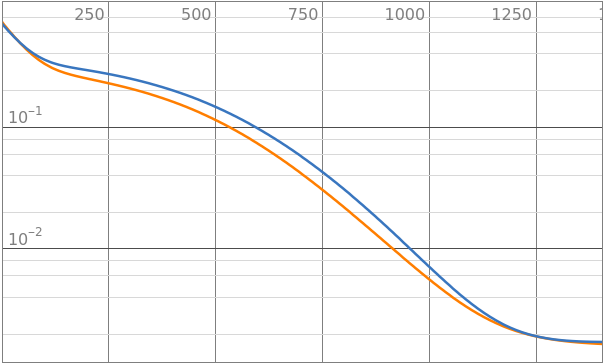
Now we can count the length of the last step series with the validation loss increasing:
In[]:=
countVLI[ntro_]:=Module[{vll},vll=Reverse[ntro["ValidationLossList"]];First[Flatten[Position[vll[[;;-2]]-vll[[2;;]],_?(#<=0&)]]]-1]
And in this case this value will be equal to one, as one would expect:
In[]:=
countVLI[trained0]
Out[]=
1
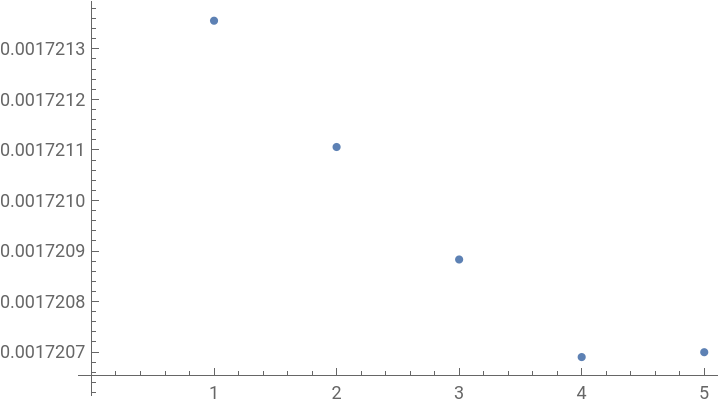
That is the training stopped after an increasing of the validation loss:
In[]:=
ListPlot[trained0["ValidationLossList"][[-5;;]]]
Out[]=
But let us set Patience1:
In[]:=
trained2=myTrainNet[2]
Out[]=
NetTrainResultsObject
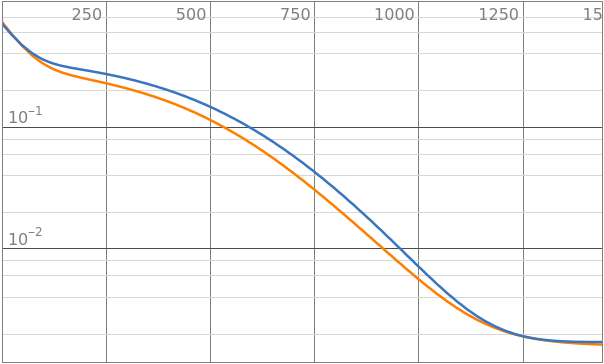
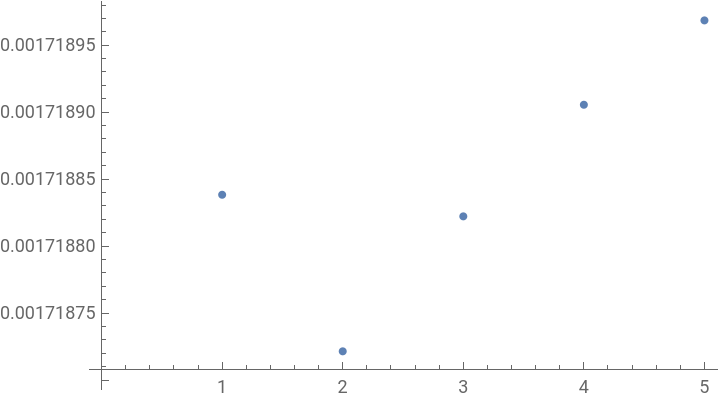
That is the training stopped after 3, rather than 2, increases of the validation losses:
In[]:=
countVLI[trained2]
Out[]=
3
In[]:=
ListPlot[trained2["ValidationLossList"][[-5;;]]]
Out[]=
For larger Patience the situation gets worse.
In[]:=
trained10=myTrainNet[10]
Out[]=
NetTrainResultsObject
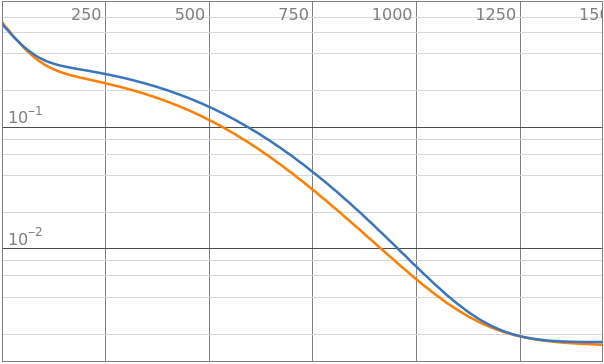
In this case
In[]:=
countVLI[trained10]
Out[]=
0
and the validation loss decreased when the training stopped.
In[]:=
ListPlot[trained10["ValidationLossList"][[-30;;]]]
Why countVLI[trainx] is not equal to Patience?