Emily and Lakisha
Emily and Lakisha
AP Research CT [Social Science]
JulianJacklin
Computational Thinking (CT) modules bridge the gap between students' emerging proficiency in subject-area content, and the their ability to use computers to address complex problems in any field. Computational thinking consists of sets of skill we may use to approach complex problems in a concise, systematic, and reproducible way. Many of these skills are found in computer science: breaking-down a problem into digestible parts, recognizing patterns, filtering out unnecessary information or prioritizing essential data, and designing a set of steps or rules to approach a solution are all skills one cultivates when working with computers; hence, computational thinking. However, this type of problem-solving can be applied to meet challenges of almost any kind.
In this module, you will be discovering racial disparities in labor market hiring practices and their implications as discussed in this module's primary document: Are Emily and Greg More Employable Than Lakisha and Jamal? A Field Experiment on Labor Market Discrimination (Bertrand & Mullainathan, 2004). Social science research is a broad group of studies aimed at better understanding human behavior and societal structures. Some questions in sociology and economics are too complex or infeasible for a single human or group of humans to figure out on their own. This is where computers—but more crucially, computational thinking—play a role. Throughout the course of this module, you will pose a research question, analyze empirical data, visualize disparities, and communicate your findings using evidence from the study.
This Computational Thinking module is intended for integration into the AP Research course.
Research Question
Research Question
Background
Background
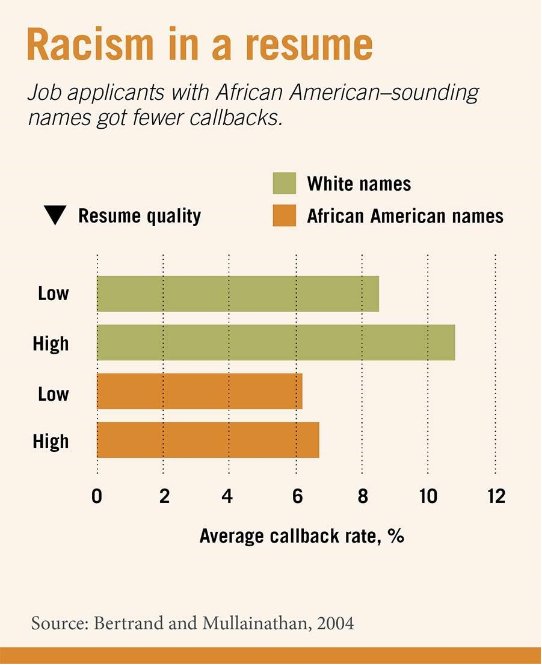
Do Black and White applicants differ in their likelihood of receiving a job callback, and does that depend on resume quality or gender? This is the central question that Bertrand and Mullainathan (2004) ask in their seminal paper, but there are several other factors, including applicants' years of experience, education levels, computer skills, military service, and neighborhood socioeconomic indicators, that can lead to different questions regarding racial discrimination in the labor market.
Consider this!
Consider this!
To generate your own question, think about:
Swapping the outcome – Instead of job callbacks , ask about differences in resume characteristics across candidate profiles (e.g., do resume features like honors or computer skills vary by race?).
Swapping the grouping variable – Compare application outcomes by geographic location (city, which looks at Boston vs. Chicago) instead of applicant gender (sex).
Change the relationship – Test whether one specific resume asset predicts a callback (e.g., years of experience) instead of comparing demographic groups.
And before finalizing, check your question:
- Can it be answered with variables that actually exist in the data?
- Is it specific (names exact variables/comparison)?
- Is there enough data in each group (as in groups of people) to compare meaningfully?
- Is this genuine research or just a quick, online search?
My Question:
My Question:
Data Collection
Data Collection
Methodology
Methodology
How do the researchers collect data? What are two important considerations for collecting said data? These can be of your own making, or directly from the study.
Import
Import
To work with our data, we need to first import it into our environment—meaning, we just need to have it on our screen, to be able to work with it. For our purposes, this data will be imported as a spreadsheet (CSV) from the cloud. Run the following line of code to view the dataset.
In[]:=
data=Import["https://www.wolframcloud.com/obj/84c36c9e-b19c-459f-81e6-40a900f03617","Dataset"]
Out[]=


How many different resumes are in this dataset? How many variables were used, and what were they? You should use the Dimension and ResourceData functions to help answer these questions
Hint! You can begin typing any function in Wolfram Language input, and info will appear that may help you understand how to use it.
Hint! You can begin typing any function in Wolfram Language input, and info will appear that may help you understand how to use it.
Data Visualization
Data Visualization
Variables
Variables
Before visualizing anything, lets first identify what variables we'd like to use to answer our research question, and take note of how they are written in the dataset (First Name is not the same as first_name—why do you think that is?).
In[]:=
grouped:=GroupBy[data,Key["INSERT GROUP VARIABLE 1"]];grouped2:=GroupBy[data,Function[row,{row["INSERT GROUP VARIABLE 1"],row["INSERT GROUP VARIABLE 2"]}]]
Graphing
Graphing
Graphs and plots allow us to communicate trends in data clearly, typically catering towards wider audiences (why might this be?). In WL, there are several ways to plot data. Using the dataset and your chosen variables, your task is to determine which of the plots below communicates trends in your data the best (i.e. which graphs work, and which give you an error).
Means:=Mean[#[All,"INSERT NUMERICAL/BINARY VARIABLE"]]&/@grouped2;rawKeys=Normal[Keys[Means]];cleanLabels=StringRiffle[#," / "]&/@rawKeys;BarChart[Values[Means],ChartStyle"Pastel",PlotLabel"Barplot",ChartLabelscleanLabels]
In[]:=
callByGroup:=Mean[#[All,"call"]]&/@grouped;rawKeys=Normal[Keys[callByGroup]];BarChart[Values[callByGroup],ChartLabelsrawKeys,ChartStyle{RGBColor[0.4,0.7,0.4],RGBColor[0.6,0.4,0.7]},AxesLabel{None,"Callback Rate (%)"},TargetUnits"Percent",LabelStyleDirective[FontFamily"Helvetica",12]]
xyPairs=Normal[#[All,{"INSERT NUMERICAL VARIABLE","call"}]]&/@grouped;lm1=LinearModelFit[Values/@xyPairs[[1]],x,x];lm2=LinearModelFit[Values/@xyPairs[[2]],x,x];Show[Plot[lm1[x],{x,Min[data[[All,"INSERT NUMERICAL VARIABLE"]]],Max[data[[All,"INSERT NUMERICAL VARIABLE"]]]},FrameTrue,FrameLabel{"INSERT NUMERICAL VARIABLE NAME","Predicted Probability of Callback"},PlotLabel"Linear Plot",PlotStyleDirective[Thick,RGBColor[0.070,0.929,0.930]],GridLinesAutomatic,PlotLabels"Group 1"],Plot[lm2[x],{x,Min[data[[All,"INSERT NUMERICAL VARIABLE"]]],Max[data[[All,"INSERT NUMERICAL VARIABLE"]]]},FrameTrue,FrameLabel{"INSERT NUMERICAL VARIABLE NAME","Predicted Probability of Callback"},PlotLabel"Linear Plot",PlotStyleDirective[Thick,RGBColor[1.000,0.276,0.395]],GridLinesAutomatic,PlotLabels"Group 2"]]
Trends
Trends
What trends or patterns seem to appear in your data? What might these say about your research question? Do your findings make sense to you intuitively?
Results
Results
Now that we've got some visualizations for our data, it is time to use statistics to make empirical conclusions in regards to our research question.
Logistic Regression: What are the odds?
Logistic Regression: What are the odds?
Logistic regression is a tool we use when dealing with variables that are binary, or have only two values. For our purposes, we will be looking at the call variable, which takes the values 1 (applicant received a call back) and 0 (applicant did not receive a call back). Ultimately, we would like to learn if an applicant is on average more likely to receive a call back if they are thought to be white, rather than black.
The following code cell has already been written and evaluated for you.
The following code cell has already been written and evaluated for you.
This result tells us that you are roughly e^(0.4318), or 1.5, times more likely to receive a call back if you are white applicant, than if your were a black applicant, based on the data of the study.
Here's something to think about: Employers want to hire people with X quality, and perhaps the white applicants just have more of those qualities than the black applicants. Is this true? We can again use logistic regression find out. By adding a covariate, or another variable into our model, we can effectively control for it. In other words, we can ask the question: assuming we have two applicants with the same X quality (education level, for instance), how much more likely are they to get a call back soley due to their race. Use the code below, and any covariate of your choosing, to come to a conclusion:
Conclusion
Conclusion
Discussion
Discussion
Given everything you have learned in this module, were you able to answer your research question? If you were able to, detail what empirical evidence you've collected that supports this claim(s).
If you were not able to adequately answer your research question, ask yourself: could I have answered my question using only the data provided? Was there something meaningful you learned about the topic regardless?
If you were not able to adequately answer your research question, ask yourself: could I have answered my question using only the data provided? Was there something meaningful you learned about the topic regardless?
Next Steps
Next Steps
How would you expand on the work of these researchers? Is there a different sample you would consider? A different research focus? Would you change how the research was conducted. Discuss this below.